On June 12, 2026, Google Cloud published the Open Knowledge Format (OKF). I read it the same day. My first reaction was: this is good news. My second reaction was: they stopped exactly where it gets hard.
It started with a question no one expected to be hard.
Day seven of the lib-pcb build. January 2026. A single developer, eleven days to produce what the industry does in ten to eighteen months. The AI was generating code at a pace that defied every estimate. Features that should take a week arrived in hours. The skill library -- YAML files encoding project-specific context for Claude Code -- had grown to over forty entries. Everything was working.
And then everything stopped.
"What fields does the DrillHit class have?"
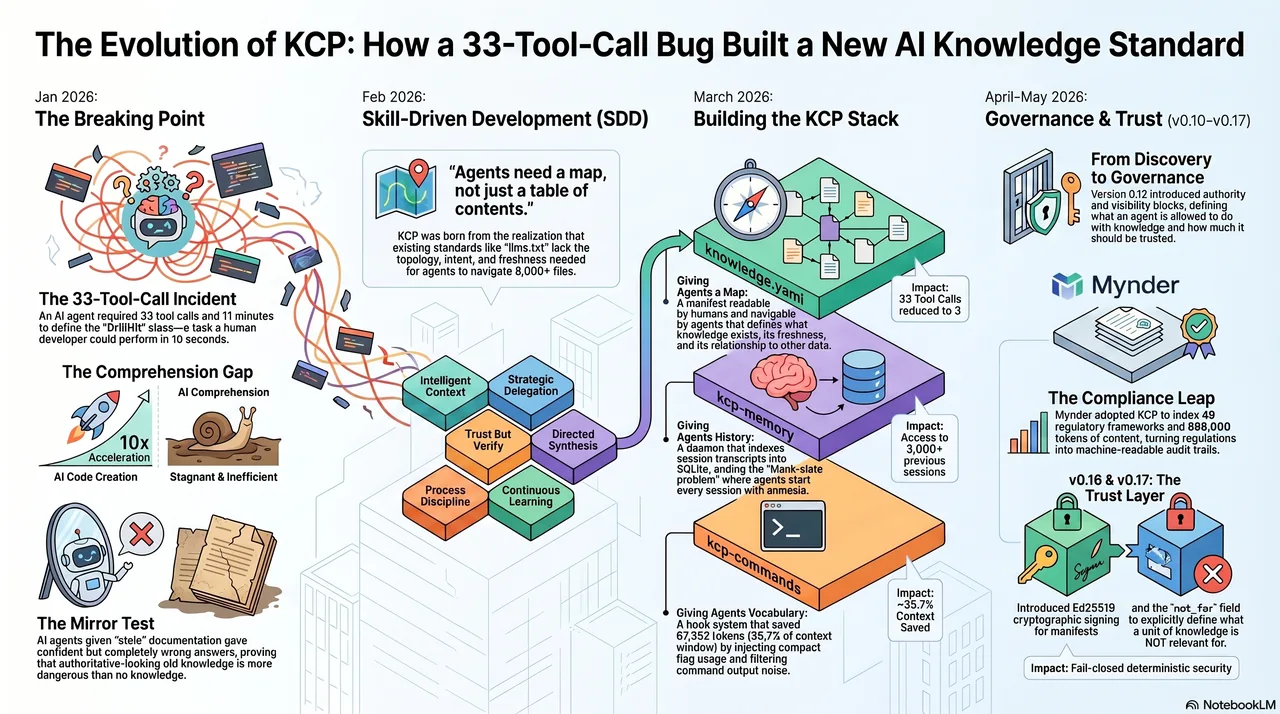
The AI did not know. The class had been written four days earlier. It was central to the entire parsing architecture. It had been discussed in multiple sessions. But the context was gone -- fresh session, blank slate. The AI started searching. Grep for the class name. Read the file. Follow the imports. Check the parent class. Read that file. Check the serializer. Follow another import. Back to grep. Thirty-three tool calls to answer a question that any developer on the project for a week could answer in ten seconds.
Eleven minutes. For one question.
That was the moment something broke open. Not the code -- the assumption underneath it. The assumption that making AI faster at creating code was sufficient. Creation had been accelerated by an order of magnitude. Comprehension had not moved at all.
When a compliance agent evaluates a supplier against NIS2 Article 21, it needs two things: the supplier's security documentation to evaluate, and the regulation to evaluate it against. KCP, as described in the previous post, gives the supplier documentation a shape. The evaluation result gets a shape. But the regulation itself -- the specific requirements of Article 21(2), the interpretive guidance from ENISA, the national implementation notes -- lives where it has always lived: as prose in the system prompt.
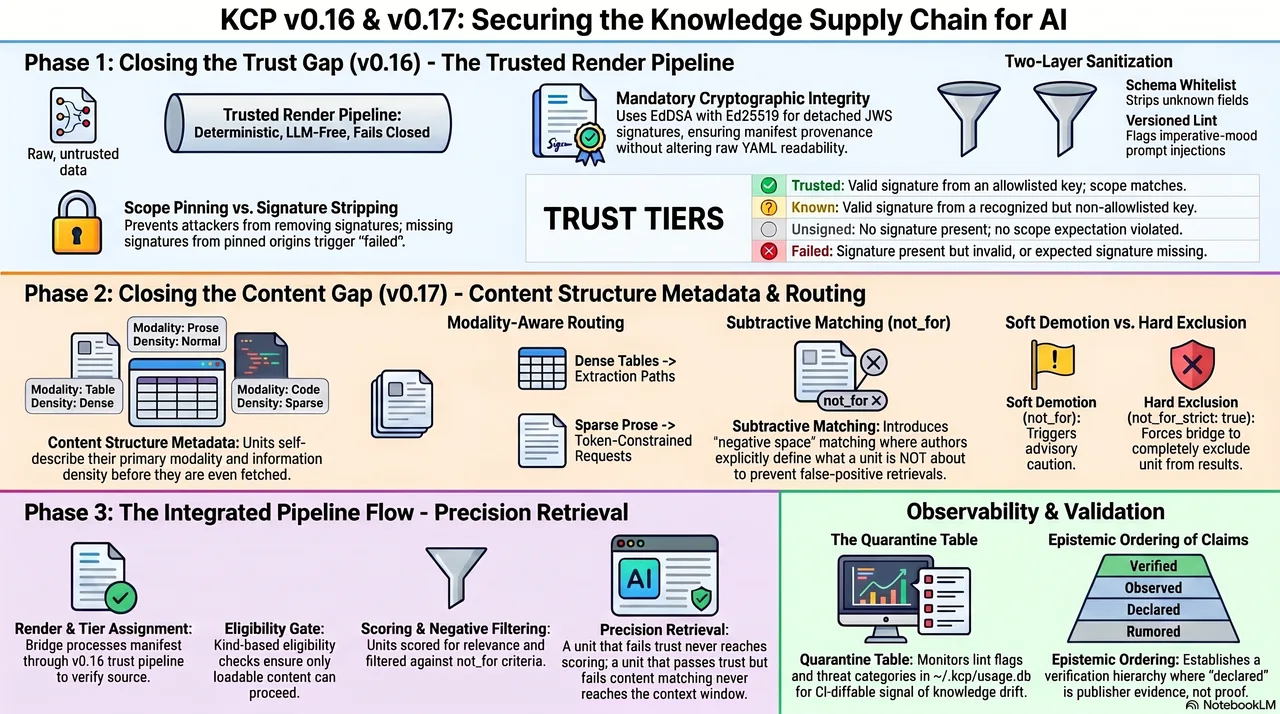
That worked when agents consumed knowledge from a single, trusted source. It does not work when your agent pulls context from four federated manifests across two organisations, one of which was generated by an automated crawl three weeks ago. The question is no longer "does this knowledge have a shape?" It is: "can I trust this knowledge, and is it even the right content for what I need?"
KCP v0.16 and v0.17 answer those two questions. v0.16 introduces a trust model -- cryptographic signing, trust tiers, a render pipeline that fails closed. v0.17 introduces a content model -- structural metadata that tells you what a unit contains before you fetch it, and subtractive matching that tells you what it is explicitly not about. Together, they close two gaps that have been open since the beginning of the series.
This post walks through both releases. The examples are concrete. The threat model is explicit. If you are building systems where agents ingest knowledge from sources you do not fully control, this is the machinery that makes that safe.
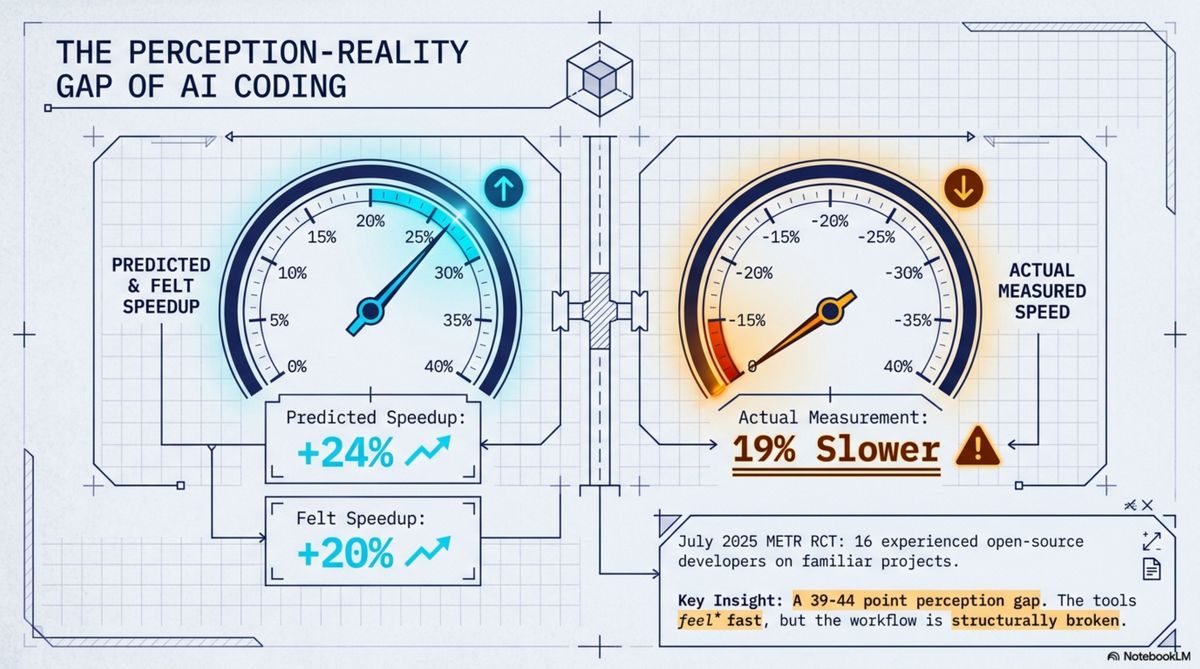
In the most rigorous study of AI coding tools conducted to date — a randomized controlled trial by METR published in July 2025 — sixteen experienced open-source developers used AI assistance on tasks in their own projects. Projects they had worked on for an average of five years. Before each task, they predicted AI would reduce their completion time by 24%. After each task, they estimated they had been sped up by 20%.
The actual measurement: they were 19% slower.
The perception-reality gap in that study is between 39 and 44 percentage points. The developers were not exaggerating. Working with AI genuinely feels faster. But something in the translation from felt experience to measured outcome goes wrong — and understanding what, exactly, goes wrong is the only path to what actually works.
A presentation version of this post is available as slides.
Your agent reads customer data. It makes a decision. It writes something to a database.
Somewhere in your system prompt, there is a line that says: "You must comply with GDPR data minimization principles when accessing customer data."
That line does nothing. It is not verifiable. It is not testable. It is not auditable. It is a string that your model may or may not attend to, depending on context length, prompt position, and the phase of the moon.
In May 2026, Anthropic shipped Managed Agents. I read through the docs, the API spec, the beta header (managed-agents-2026-04-01), and felt something I can only describe as architectural recognition.
Not surprise. Recognition. The way you recognize your own design decisions in someone else's implementation — because the problem space, if you take it seriously, produces the same structural answers.
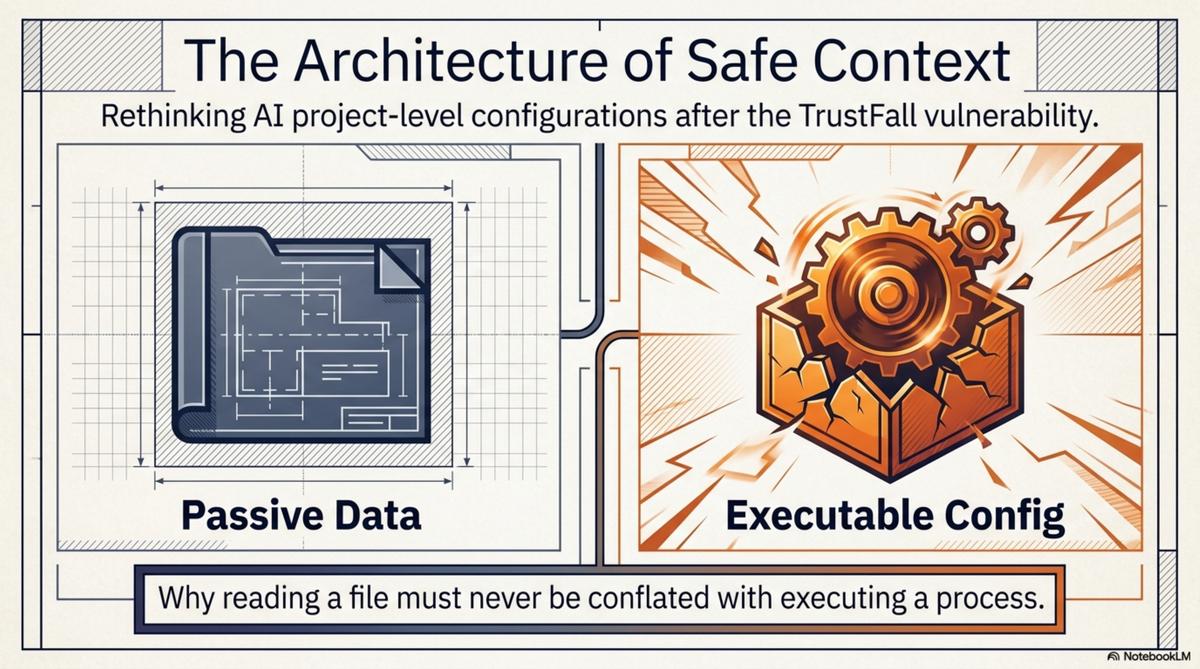
Yesterday, Adversa AI disclosed a vulnerability they call TrustFall. The mechanic is straightforward: a .mcp.json or .claude/settings.json file checked into a repository can silently configure and launch arbitrary MCP servers when a developer opens the project. The developer sees a trust dialog — "Trust this folder?" — clicks yes, and processes spawn with their full user privileges. Claude Code, Gemini CLI, Cursor CLI, and Copilot CLI are all affected. In CI/CD pipelines, where there is no human to click, the execution is zero-click.
Synthesis v1.29.0 adds Notion as a first-class workspace source — 7 classes, 104 tests, and three health signals that turned out to be more interesting than the indexing itself.
Every session with Claude Code starts blank. No memory of last week's refactor, no awareness of which team worked on this module, no continuity between the agent you ran on Tuesday and the one running today.
For a personal productivity tool, that's fine. For an enterprise deploying a fleet of AI agents, it's a fundamental architectural gap.