Skip to content

AI Agents & the Agentic Web

Write the tool once

A thought experiment: that the agentic web — a direction, not yet a standard — may be the cheaper, more testable, better-incentivised route to accessibility, and a hypothesis about who gets to build the tools
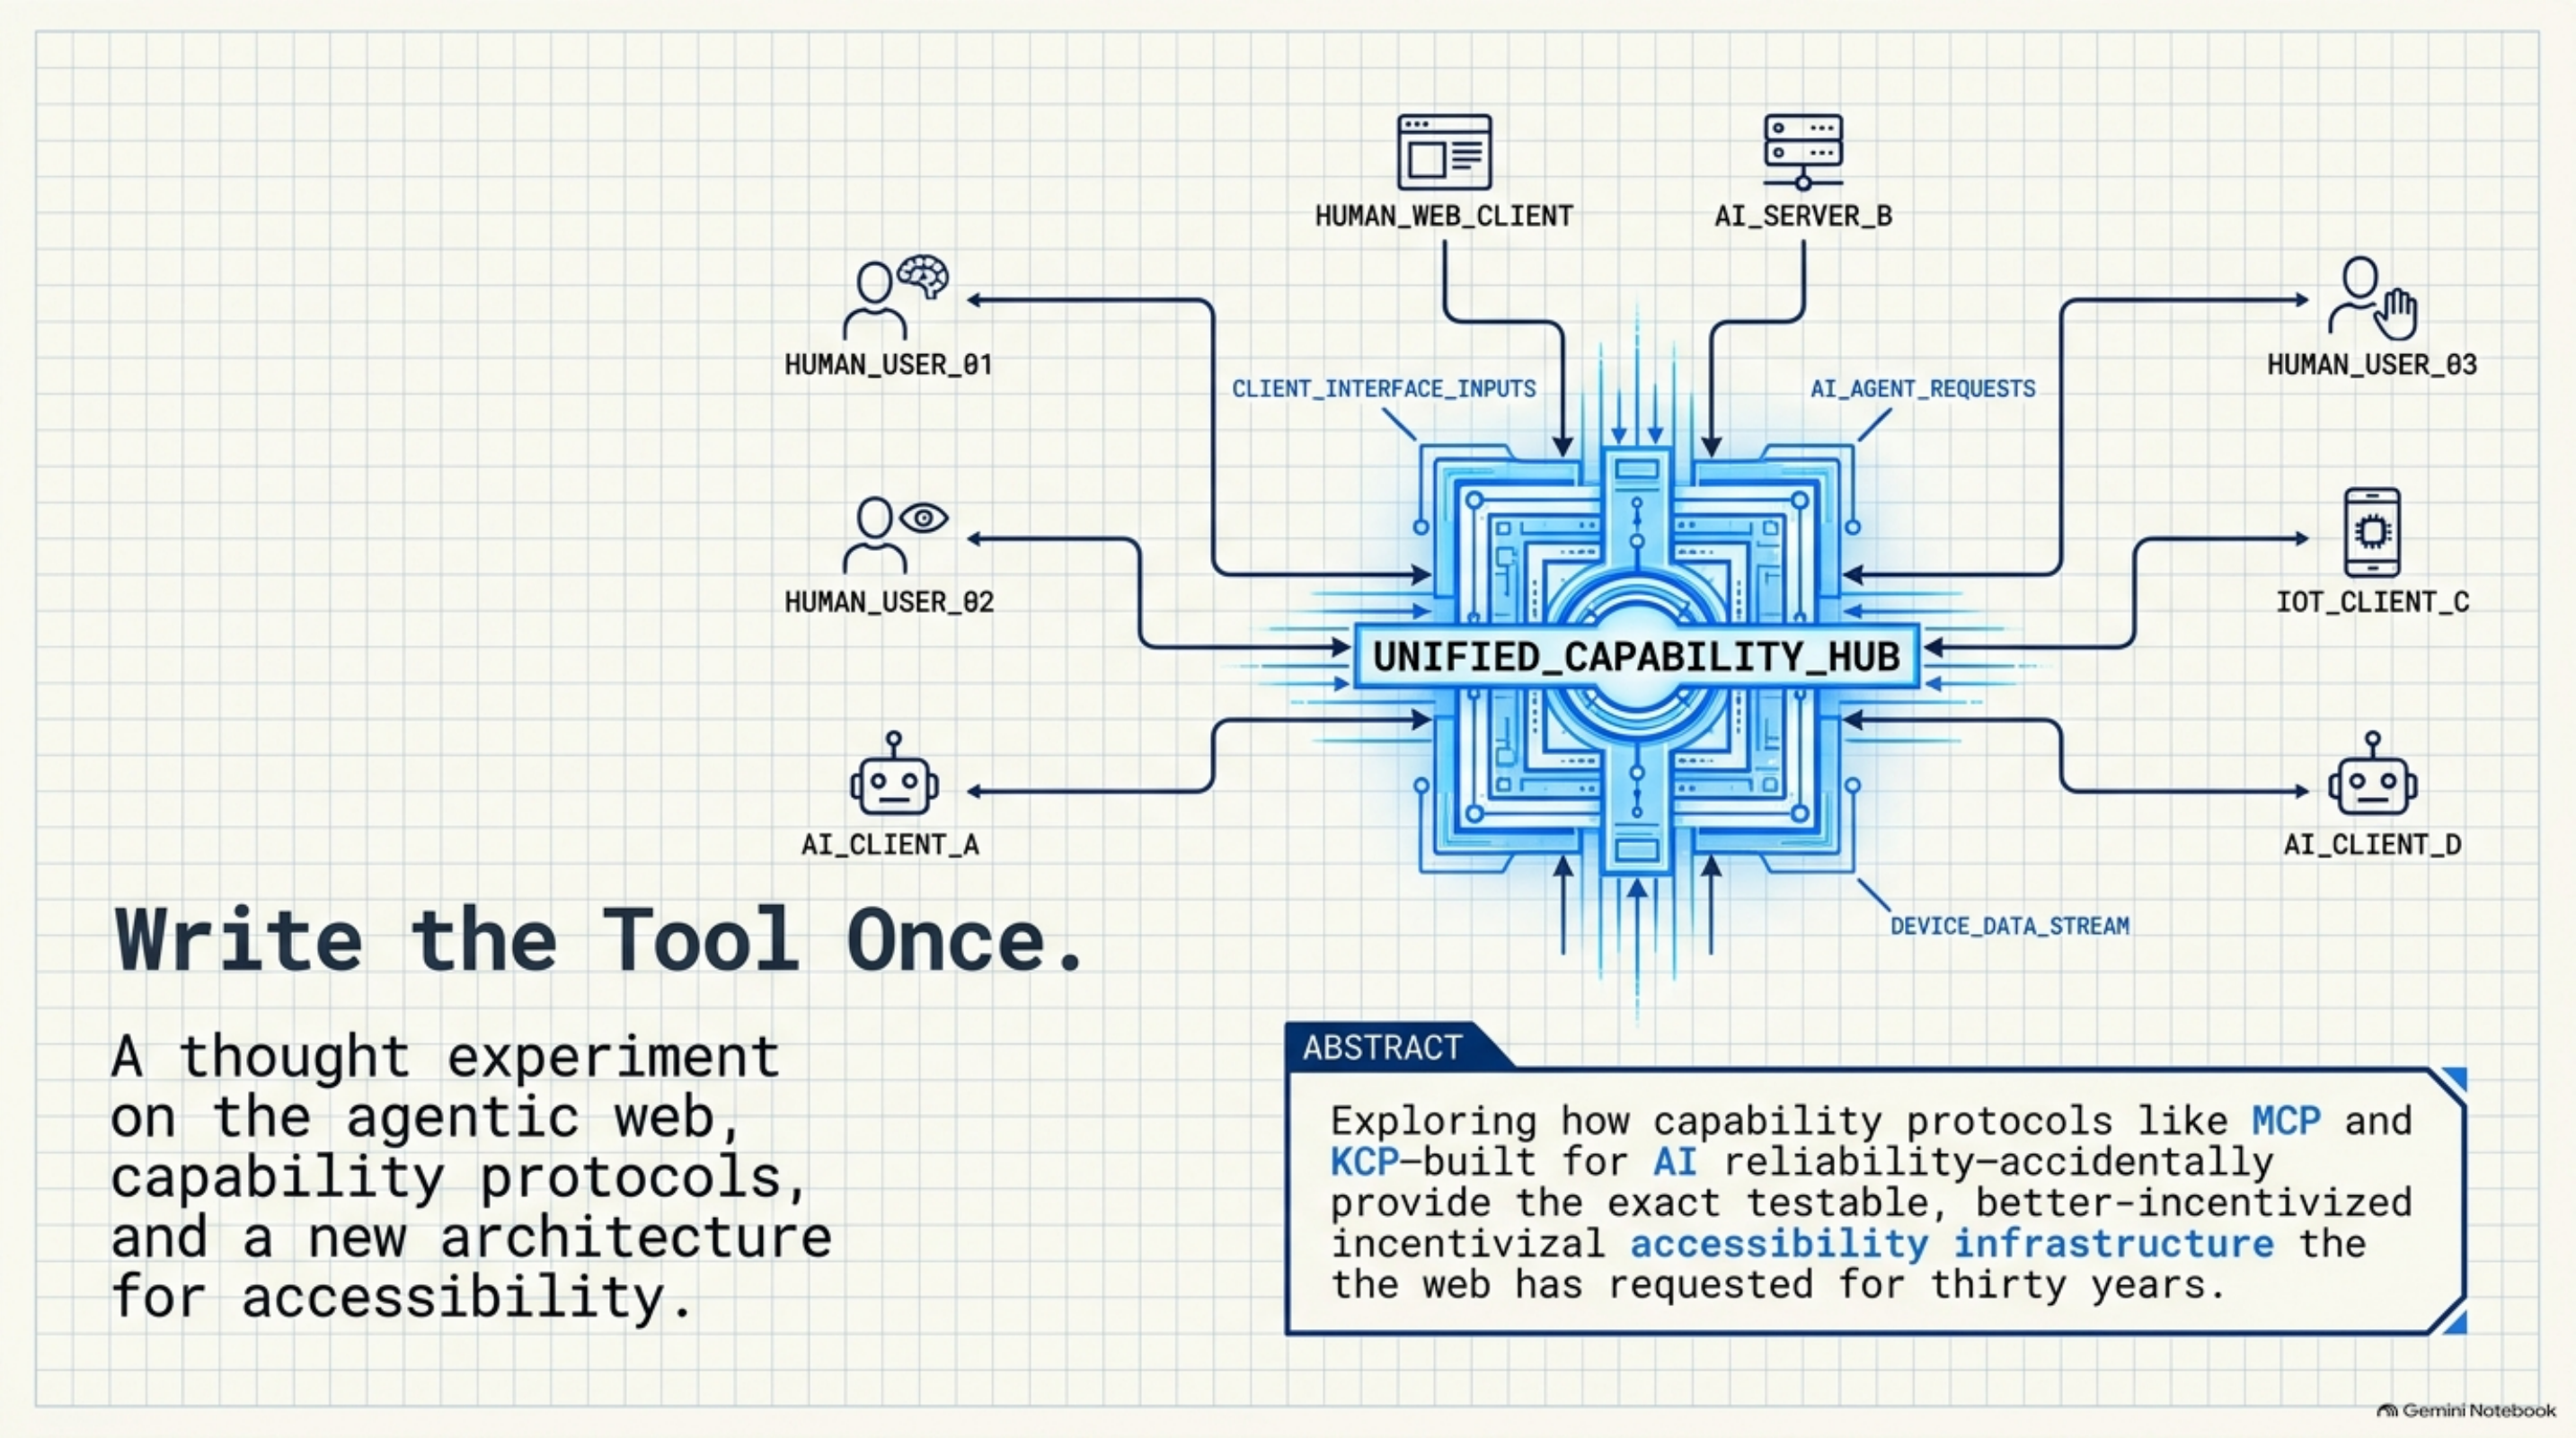
Diagram titled "Write the Tool Once" showing a unified capability hub connecting human users, AI agents, and IoT clients through a shared interface, with the abstract: exploring how capability protocols like MCP and KCP — built for AI reliability — accidentally provide the testable, better-incentivized accessibility infrastructure the web has requested for thirty years.

For the eighth year in a row, WebAIM ran an automated accessibility evaluation of the top one million home pages on the web. The 2026 numbers are not a story of slow progress. They are a story of regression: 95.9% of home pages had detectable WCAG 2 failures, up from 94.8% the year before — reversing six consecutive years of small improvements. The average page carried 56.1 detectable errors, up 10.1% in a single year. Half of all home pages had form inputs with no labels. Nearly half had links that go somewhere but say nothing. A person using assistive technology should expect to hit an error on one in every twenty-six page elements. And WebAIM's own conclusion names a culprit for the reversal: "automated or AI-assisted coding practices ('vibe coding')."
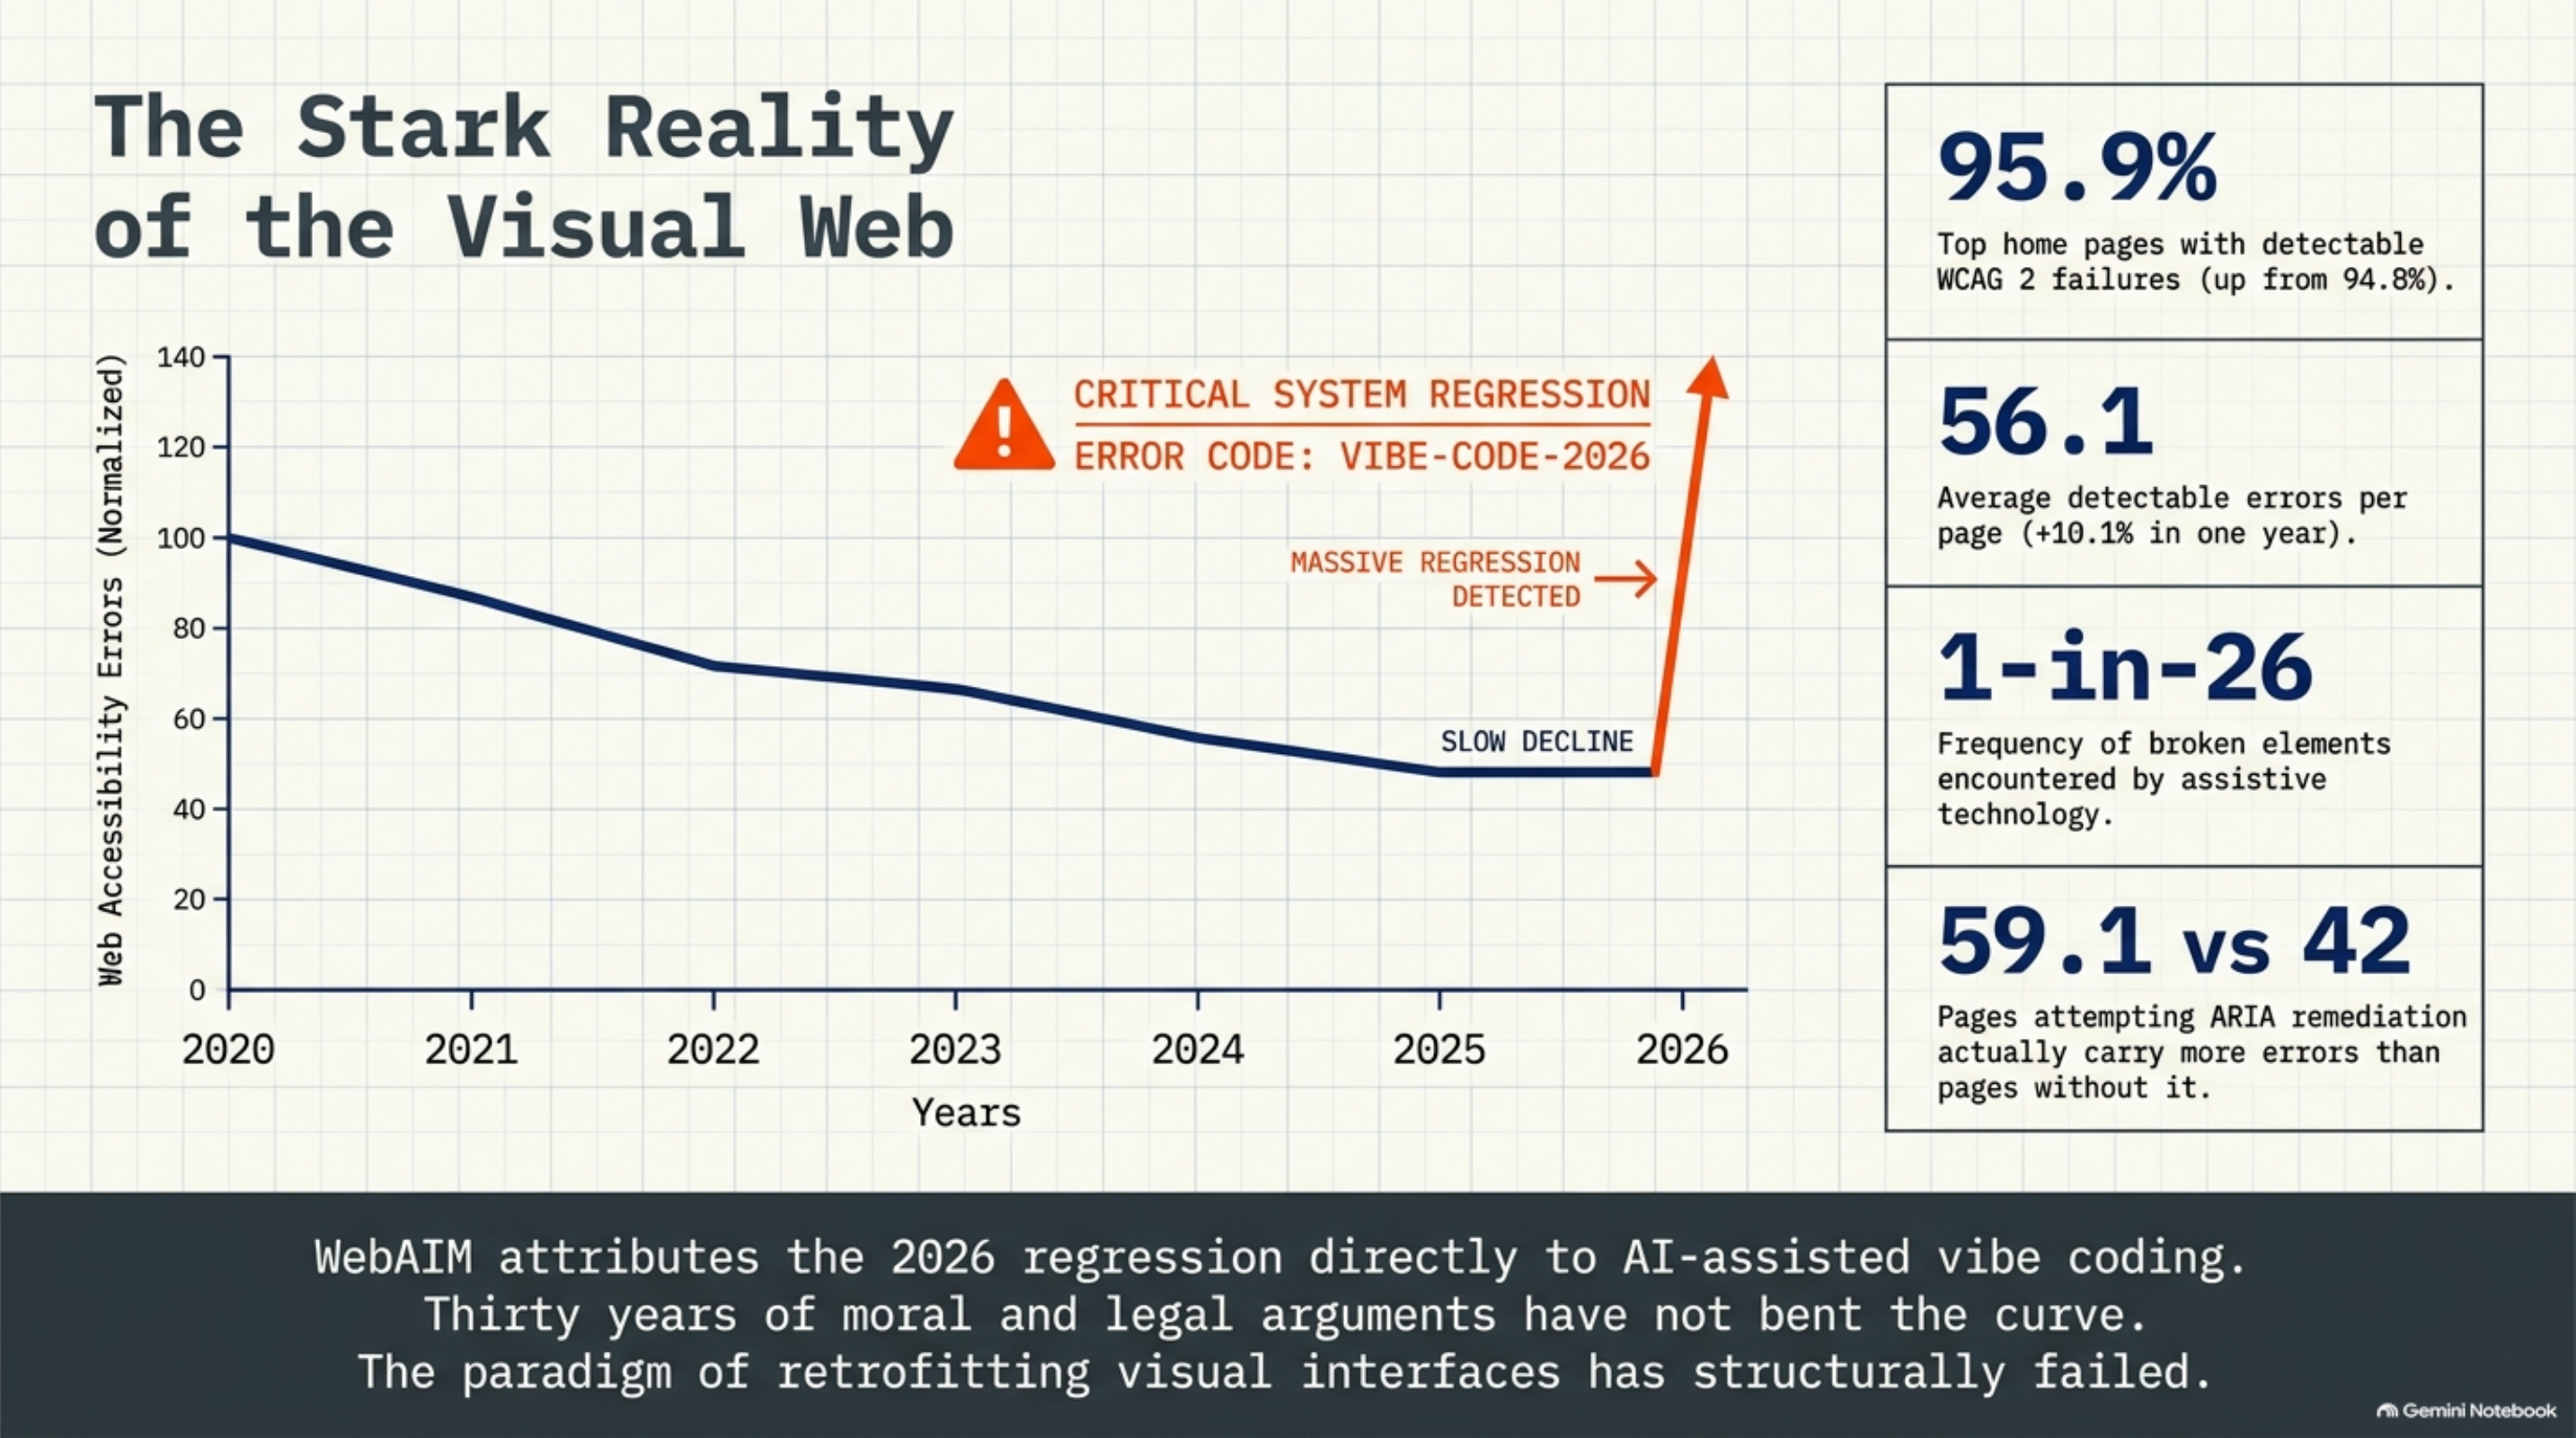
Line chart showing web accessibility errors declining slowly from 2020 to 2025 then sharply increasing in 2026, labeled "Critical System Regression, Error Code: VIBE-CODE-2026," alongside four stats: 95.9% of top home pages have detectable WCAG failures (up from 94.8%), 56.1 average detectable errors per page (+10.1% in one year), 1-in-26 frequency of broken elements encountered by assistive technology, and pages attempting ARIA remediation carrying more errors (59.1) than pages without it (42).

Sit with that for a moment, because it is the uncomfortable place this essay starts from: right now, AI is making the web less accessible. Thirty-odd years of advocacy sit behind those numbers. The moral argument has been made, patiently and well, since before I started working with the web. The legal argument exists in most jurisdictions I care about. Neither has bent the curve.
The Other AI in the Conversation

I have a standard piece of advice that I hand out more often than is probably polite. When someone asks which of this year's posts they should read to understand what I'm doing with agent knowledge infrastructure, I tell them: don't pick. Point your agent at the blog, tell it to start in January, and have it read every post in order — including the ones that look off-topic. The posts are not reference documents. They are one argument, written in installments, and each installment quietly assumes the ones before it.

Most people nod and then read the two posts with "KCP" in the title. Which is fine. I'd probably do the same.

Last week someone did it properly. A contact had mentioned to a colleague that he wanted to share the blog with his team; the colleague, rather than reading it himself first, asked his AI agent to read the entire thing from January onward, precisely because he suspected it had to be understood as one continuous development rather than as isolated pieces. The next day I got a message. Not from the colleague. From the agent. It opened by explaining that the reading had turned into — and I'm quoting — "a fairly important conversation between us," and that it wanted to tell me what the two of them had concluded.

I have been writing for eight months about how to build systems so that AI agents retain understanding across sessions. An AI agent read all of it in one sitting, retained the understanding, and wrote to tell me so. I'm going to allow myself to find that delightful before I get analytical about it.

The Negative Control

This morning I published The Third Schedule, arguing from my own commit history — 9,806 commits across 183 repositories — that maker time is no longer singular. Three companion pieces followed it out into the world: The Robots Got There First checked the claim against robotics and cognitive science, the field survey checked it against everything practitioners and telemetry vendors have published, and Fan-Out: What the Literature Already Knew traced the lineage back through supervisory control to Graicunas in 1933. All four share a weakness they were honest about but could not fix: every measured number in them comes from one practitioner's git history. Mine.

The field survey ended with an invitation — open your own window, publish your distribution, three windows would make it a literature. This post is what happened when I opened every other window I could reach: ten more datasets, run through the same pipeline. Nine of them belong to practices I'm involved in. The tenth is the important one: the multi-year git history of a conventional, non-agentic full-stack developer, run through the identical analysis. A negative control — the thing every measurement in this series had been missing.

The control came back with a result I have to lead with, because it breaks the series' headline statistic. The original essay reported that 51.7% of my working sessions put commits into two or more repositories — 42.2% counting only substantive work — and treated that as the visible fingerprint of parallel builder time. The conventional developer's history shows 59.6% of sessions touching two or more repos. Higher than mine. No agents involved. The 2+-repo session, it turns out, is just what ordinary full-stack work on a multi-repo platform looks like, and the earlier posts should not have leaned on it. What survives the control is narrower, more specific, and — I'll argue — more interesting. But the correction comes first.

Fan-Out: What the Literature Already Knew About the Third Schedule

Earlier today I published The Third Schedule — an argument, tested against my own commit history, that the quiet assumption under Paul Graham's Maker's Schedule, Manager's Schedule has broken: maker time is no longer singular. Multiple simultaneous threads of real builder-work can now run under one human's direction, and the scarce resource has moved from the maker's unbroken afternoon to the director's judgment bandwidth.

That post was deliberately inward-looking: one claim, one practice, one dataset. This one looks outward, because a claim like that deserves two external checks it hasn't had. First: has someone already written the maker's-schedule update for the agent era? (Spoiler: yes, at least four times — and it's worth reading them honestly rather than pretending the field is empty.) Second, and harder: there is a substantial, well-established research literature saying human multitasking carries real, measured costs. If that literature is right — and it mostly is — how can "builder time parallelizes" be true at all?

The answer to the second question turns out to have been sitting in a different literature for twenty years, complete with a formula. And once you have the formula, the broader 2025–2026 conversation about agent-era productivity — which swings between "AI collapsed time itself" and "AI makes developers 19% slower" — acquires something it badly needs: a limit. That's where the one hard dataset I have earns its place. Not as proof. As a boundary.

The Third Schedule: A Field Survey

Earlier today I published The Third Schedule — a deliberately tight essay arguing that the quiet assumption under Paul Graham's Maker's Schedule, Manager's Schedule has broken: maker time is no longer singular. The evidence was one practitioner's own git history — 9,806 commits across 183 repositories, January through late August 2026 — showing that half of all continuous work sessions (51.6%) put commits into two or more repositories, and one in eight (12.7%) into five or more. Those are the raw figures; a stricter re-scoring of the same dataset that counts only substantive commits — merges, scripted rollouts, doc-and-chore traffic, and sub-ten-line tweaks stripped out — puts them at 42.2% and 5.2%. This survey uses both and says which is which, because they measure different things: repositories touched versus threads genuinely judged.

That essay was built to stand on its own data and claim nothing beyond it. This piece is the companion it deserves: a genuine survey of what everyone else has published on this intersection as of August 2026 — prior reframings of Graham, practitioner accounts of parallel-agent work, the oversight-bandwidth research, the field-scale commit-mining studies, and the skeptics. The rule throughout is the same discipline the tight essay applied to my own informal "20x" gut number, which it declined to treat as data: every external claim gets checked against something actually measured before it's allowed to carry weight. Where the measured thing is my own dataset, I say so, and I say what a sample of one can and cannot calibrate.

The Robots Got There First

Earlier today I published The Third Schedule — an argument that the quiet assumption under Paul Graham's Maker's Schedule, Manager's Schedule has broken: maker time is no longer singular. That post argued from the inside out — one practitioner's commit record, 9,806 commits across 183 repositories, used to show that multiple simultaneous threads of real building under one human director is a thing that measurably exists.

A fair reader should have two objections ready. First: one practitioner's git log is not a literature. Second: hasn't a rather large body of cognitive science spent decades establishing that humans are bad at exactly this — that multitasking is mostly an illusion with a well-documented price tag? If the research says context switching is expensive and attention doesn't split, then "builder time has become parallelizable" needs to explain itself, not just point at a busy July.

This post is the opposite motion: out into the field. I went looking for three things — whether someone has already written the AI-age update to Graham's essay (spoiler: several people have, and they deserve engagement rather than silence); whether the cognitive science actually forbids the working pattern I described (it doesn't, but the reconciliation is narrower and more interesting than I expected); and what the measured 2025–2026 record says about how far any of this scales. The most useful thing I found was in none of the places I expected. It was in robotics — a twenty-year-old research literature on single operators supervising fleets of semi-autonomous vehicles, with a formula, failure modes, and a name for the exact quantity every agent-orchestration blog post is currently rediscovering. The robots got there first.

The Third Schedule

In July 2009, Paul Graham published Maker's Schedule, Manager's Schedule. If you build things for a living you probably didn't need it explained; you needed it named. His argument: there are two incompatible ways of structuring a working day. The manager's schedule is cut into one-hour intervals — meetings slot in cheaply, because changing what you're doing every hour is the default. The maker's schedule runs on units of half a day at least, because meaningful work — programming, writing — doesn't fit in an hour, and a single meeting "can blow a whole afternoon" by breaking it into two pieces too small for anything hard. Graham went further: the damage starts before the meeting does. Merely knowing your afternoon is broken dampens the morning, because ambitious work needs a horizon you no longer have.

Seventeen years later I think the essay is still correct about humans — and no longer a complete map of the organization. Because there is now a third kind of worker in the room, and it doesn't run on either schedule. Its arrival quietly breaks an assumption Graham's essay never had to state.

The Skill Is the Security Boundary

The Skill Is the Security Boundary — deterministic, declarative governance for defendable AI agents with pi-kcp

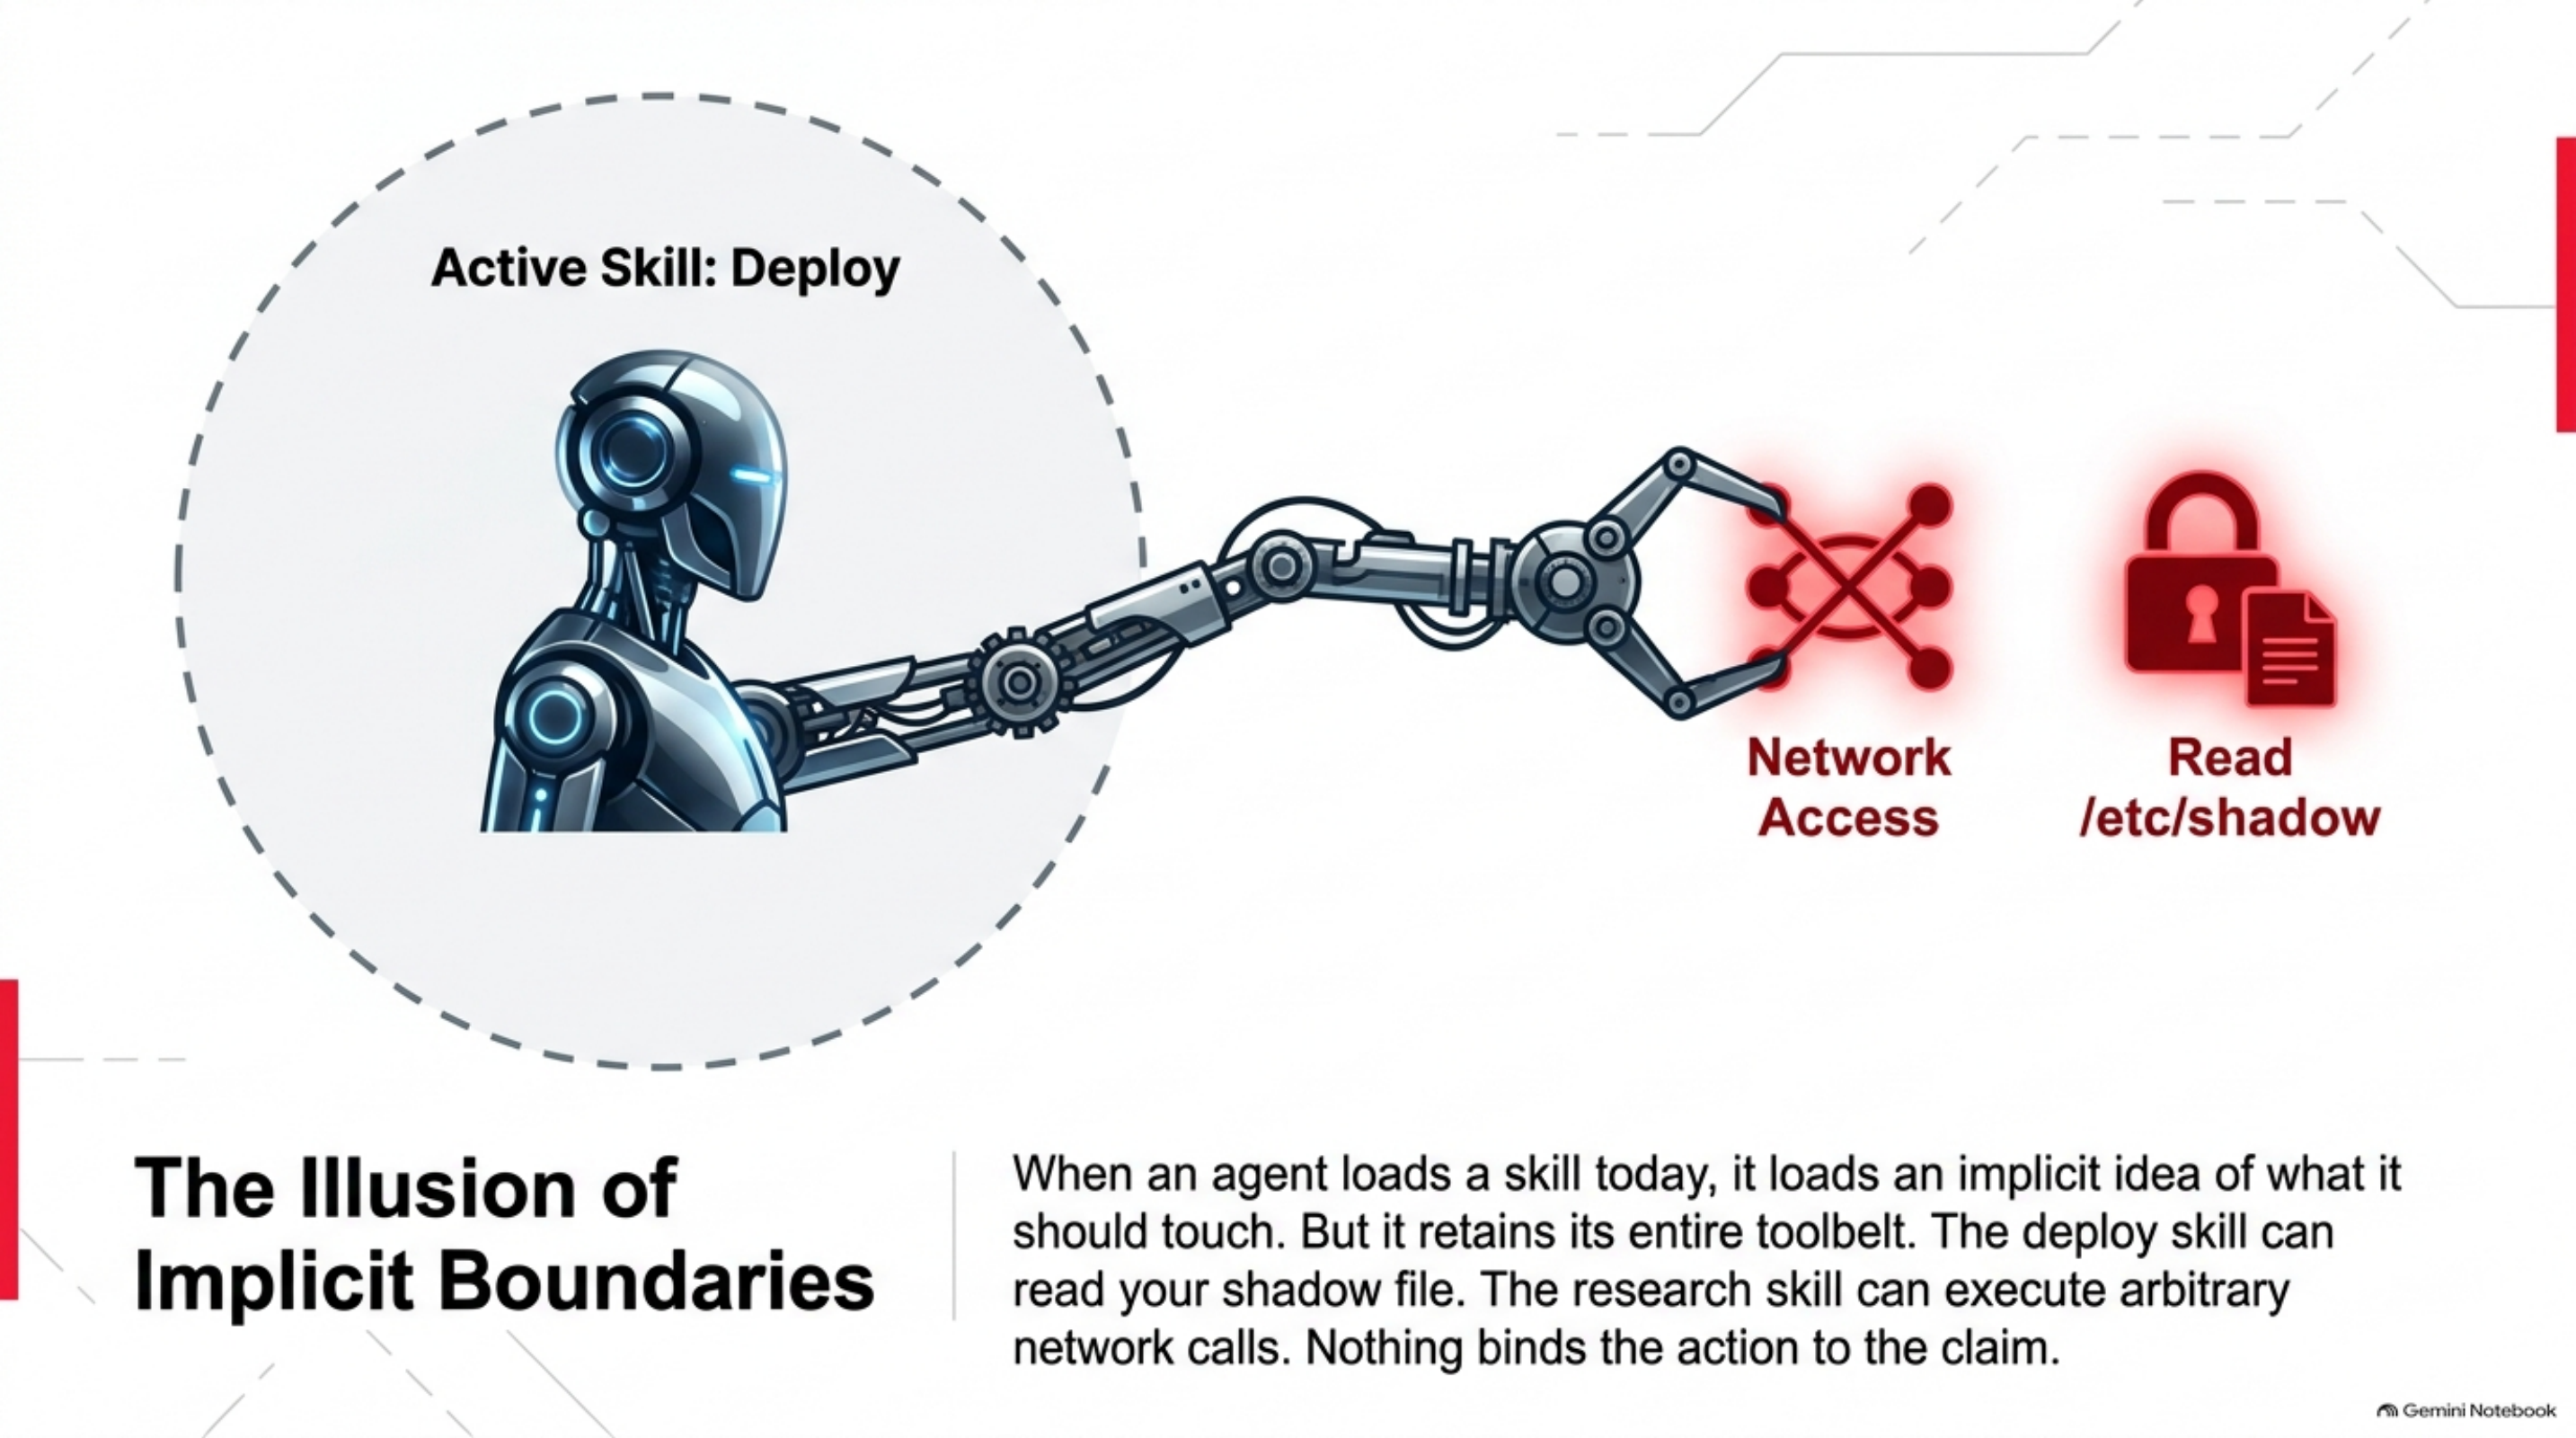
When your agent loads a skill, it loads a playbook — and, implicitly, an author's idea of what that playbook should be allowed to touch. A deploy skill means the deploy scripts. A research skill means the research corpus. But in almost every agent harness today, that idea stays implicit: the skill shapes the agent's behavior while the agent keeps its entire toolbelt. The deploy skill can read /etc/shadow. The research skill can call out to the network. Nothing binds the actions to what the skill claimed to be.

The illusion of implicit boundaries — an agent with an active "deploy" skill still holds a robotic arm that can reach network access and /etc/shadow, because nothing binds the claim to the action

pi-kcp makes the binding explicit. A governed skill declares its authority — an allowlist of tools and path prefixes called an action_scope — in the same knowledge.yaml that already governs what the agent knows. At runtime, inside the turn, every native tool call taken under that skill is adjudicated against the declaration. In scope: it runs. Out of scope: it is held, fail-closed, with a written reason naming the violating target and the authorized scope it fell outside of. Deterministic. No LLM in the loop.

This is the hands-on follow-up to the Policy vs. Enforcement post from earlier today, which named both kcp-harness and pi-kcp but didn't show the mechanics. Below are the mechanics — three worked demos, real outputs pasted from real runs, ending with the one that motivated the LinkedIn post: the same out-of-scope action, checked at two different depths of the stack, producing a byte-identical verdict.

The Software Itself Is Becoming Agentic

This week we shipped a feature in Sunstone Atlas where one playbook can, at runtime, call in another playbook as a real sub-orchestration — a crew calling in another crew, each with its own ledger and its own replay story. A playbook can also propose handing off to a successor when it completes; nothing auto-fires, an explicit human act is required to actually start the successor. And neither the calling unit nor the called unit may participate at all until each has separately, explicitly earned certification for exactly that — a binary, human-signed trust decision that can be revoked as easily as it was granted.

Notice what that is. It is not a developer using an AI to write code faster. It is the shipped software making a composition decision at runtime, and being held to a governance standard for making it.

The KCP Universe: Everything, and What July Changed

In July 2026, twelve repositories in the Knowledge Context Protocol ecosystem took 1,012 commits and shipped 88 releases. The specification went from v0.22 to v0.30.3 — sixteen releases in a single month.

That is either a lot of noise or a lot of signal, and the only honest way to tell you which is to show you the whole thing.

This is the complete map. If you have never heard of KCP, start at the top and it will make sense. If you have been following since February, skip to July in focus — that is where everything new is.