Skip to content

AI Agents & the Agentic Web

The KCP Universe: Everything, and What July Changed

In July 2026, twelve repositories in the Knowledge Context Protocol ecosystem took 1,012 commits and shipped 88 releases. The specification went from v0.22 to v0.30.3 — sixteen releases in a single month.

That is either a lot of noise or a lot of signal, and the only honest way to tell you which is to show you the whole thing.

This is the complete map. If you have never heard of KCP, start at the top and it will make sense. If you have been following since February, skip to July in focus — that is where everything new is.
Same Blueprint, Different Doors

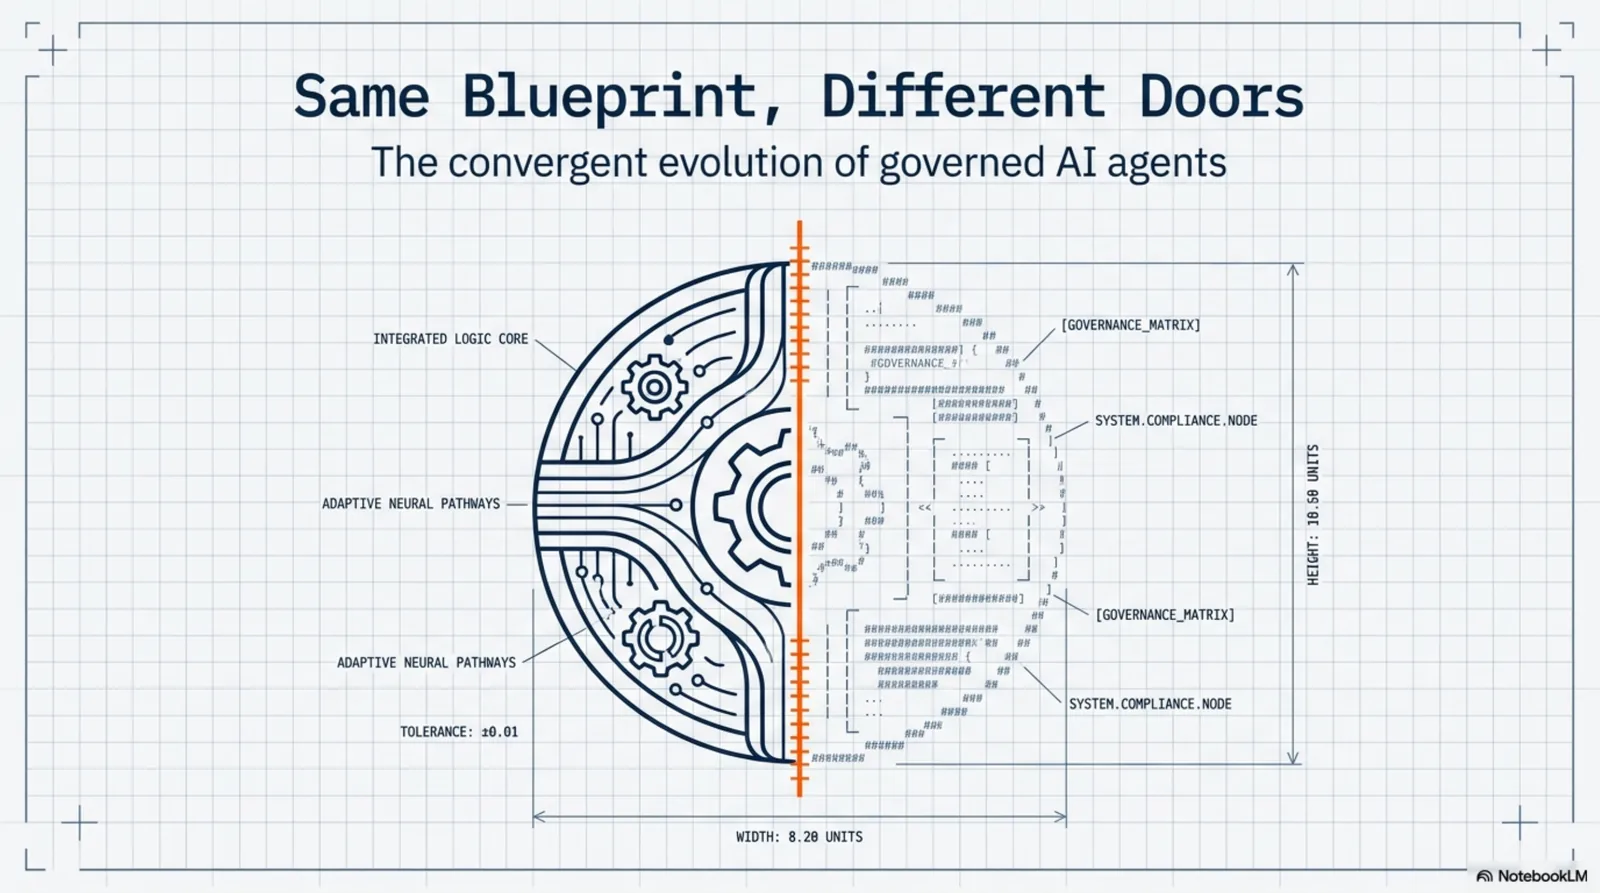
Same Blueprint, Different Doors — the convergent evolution of governed AI agents, rendered as an engineering blueprint

Anthropic published a long, careful writeup of how they built self-service data analytics on Claude internally — the system that lets anyone at the company ask a business question in plain English and get back a governed, provenance-tracked answer. 95% of their analytics queries are now automated this way, at roughly 95% aggregate accuracy.

We read it the way we read anything that touches how agents know things: looking for where we were wrong.

We found something else instead. Strip away the domain — theirs is a data warehouse, ours is a codebase and a governance practice — and the architecture underneath is close enough to feel less like inspiration and more like recognition. Two teams, no contact, building the same shape from opposite doors.

The Agent That Knows What It Knows

The Agent That Knows What It Knows — moving AI procedural memory from flat grep to a living protocol

Here is a confession. Our AI development rig — the one we call ExoCortex — has 644 skills: little packets of procedural memory that tell it how we deploy, how we review, how a specific client's CI is wired, how to publish to this very blog. And until this week, the way it found the right one, out of 644, was grep.

Keyword match against a flat index. No ranking. No freshness. When a query touched a common word, it got back a pile of candidates and had to read through them to guess. We only really noticed the cost the day we discovered that one of the skills it leans on daily had sat three weeks stale — describing a system four pull-requests out of date — and nothing, anywhere, had flagged it.

An agent that can't tell which of its own memories is rotting is not, in any deep sense, remembering. It's hoarding.

The AI Agent That Keeps the Receipts

A reveal — the defendable agent: a new kind of AI agent that keeps a receipt for everything it does. Not a log written afterward — a written, checkable verdict produced at the moment it reads a document, runs a playbook, reaches a conclusion, takes an action, or spends a dollar. Built, open-source, and running. Here it is.

Overnight, with no human watching, an AI agent read a stack of customer records, downgraded an account, and paid a data broker $50 for a report. On Thursday, your compliance officer walks over: What did it read? Why those documents? How sure was it? Who approved the downgrade? And what, exactly, did it spend our money on?

Your AI Agent Just Did Something. Can You Prove It Was Okay?

A new kind of agent — the defendable agent — is roughly 85–90% built. Here's the complete picture, one organ at a time.

On Tuesday, an AI agent called Nora followed the risk-assessment playbook, drafted an assessment for a customer account, and downgraded their status. On Wednesday the customer complained. On Thursday your compliance officer walks over: What did Nora read? Why those documents and not the newer policy from March? What playbook did she follow — the current one? How sure was she? Which human signed off, under which policy?

A Firewall for What Your Agent Knows

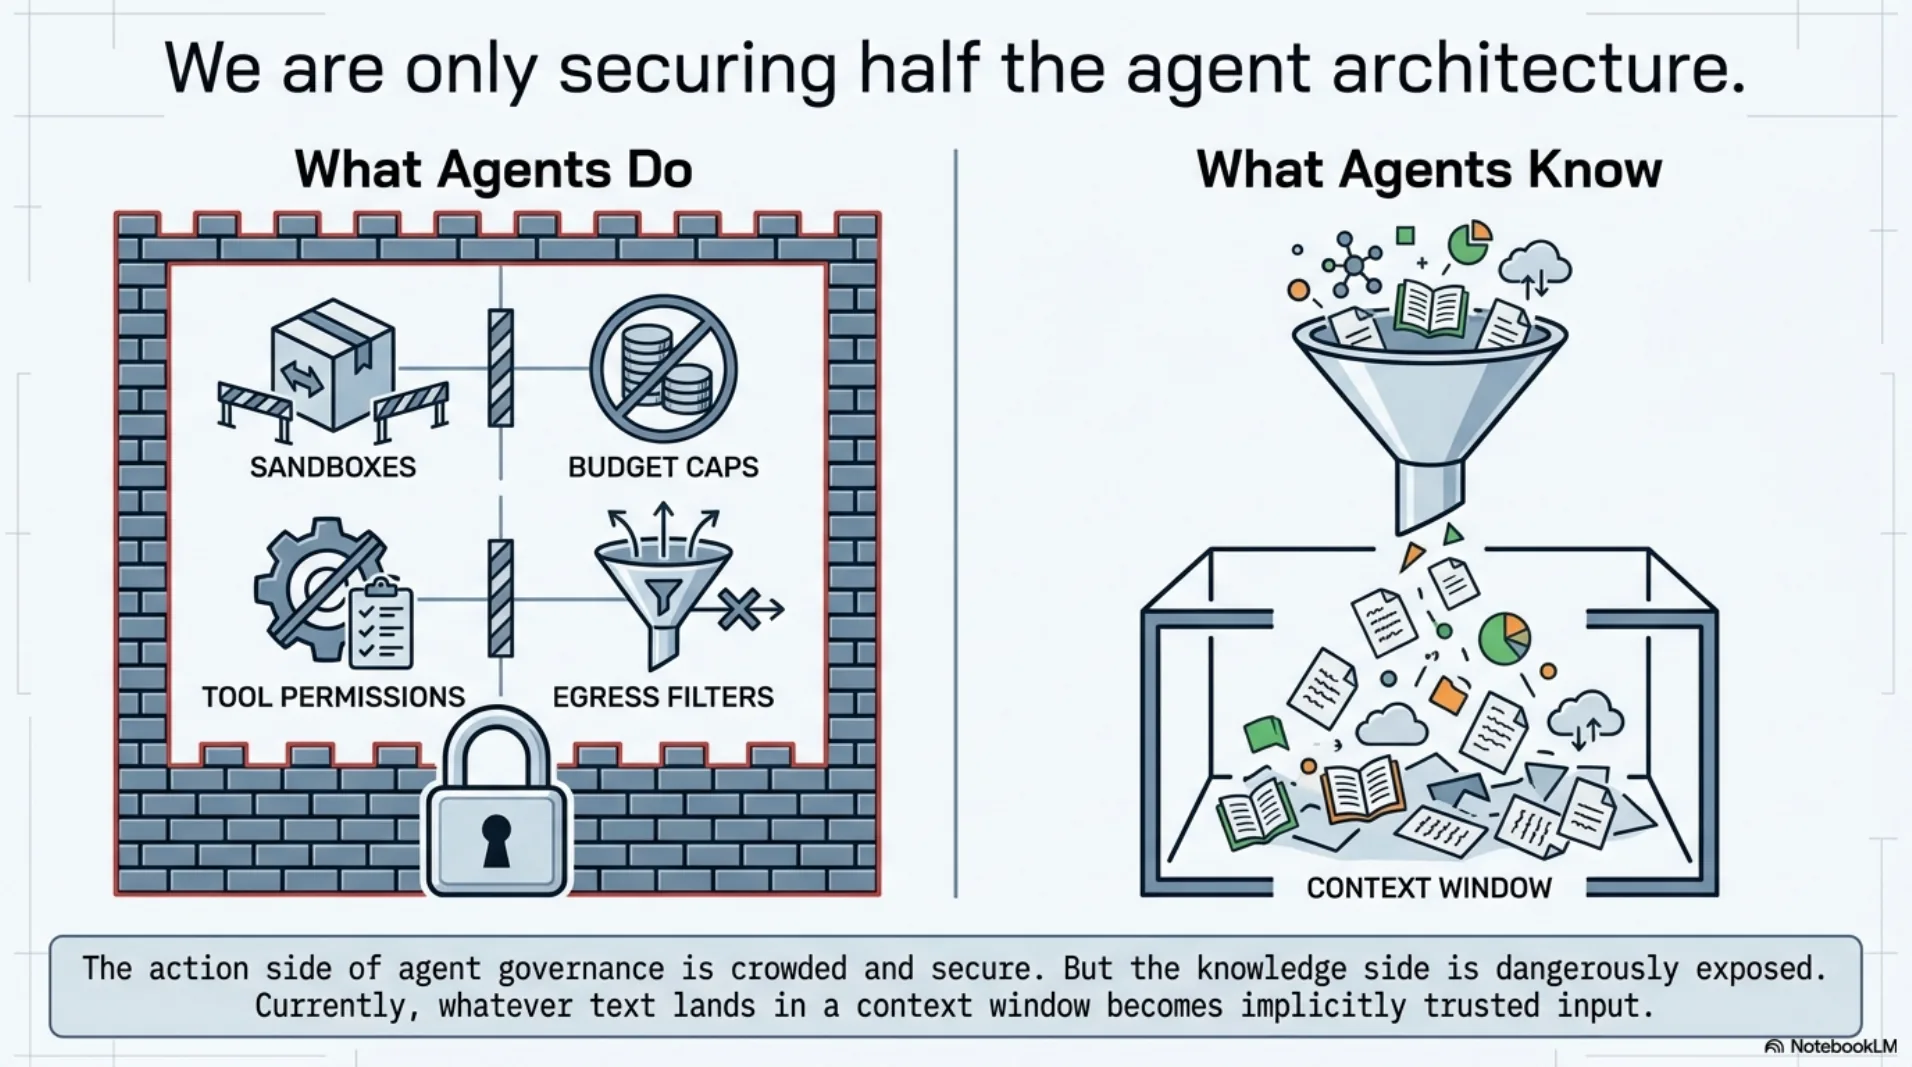
Everyone is building firewalls for what agents do. Sandboxes, budget caps, tool permissions, egress filters — the action side of agent governance is getting crowded, and that is good news. But almost nobody is building firewalls for what agents know. Your agent's context window is an unauthenticated ingestion pipeline: whatever text lands in it becomes, functionally, trusted input. If someone edits a policy document, swaps a mirror, or serves your agent a stale copy of the rules, no sandbox in the world will catch it — because nothing wrong ever executed. The agent just knew the wrong thing.

Split panel: the action side of agent governance — sandboxes, budget caps, tool permissions, egress filters — behind a locked brick wall, while on the knowledge side an open funnel pours unverified documents straight into the context window. We are only securing half the agent architecture.

This post is the hands-on companion to Two Halves of the Governance Problem. That one argued the thesis; this one is a tutorial. In about ten minutes, we take two markdown files and give them a declared, signed, tamper-evident boundary that an agent verifies before loading a single byte. Every command output below is pasted from a real run.

Defensible Agents: When Every Gate Writes Its Verdict

Two weeks ago we shipped an agent that plans deterministically and told the vibes-based era to end. The argument was real — a pure-function planner, zero-token navigation, scored reasons for every unit selected or skipped. But one question kept coming up, and it was fair:

"The plan says it skipped something. But why did gate 3 reject it and not gate 7? What was the actual decision path?"

The plan was evidence. But it was a verdict without a trial transcript.

Today kcp-agent 0.10.0 ships the trial transcript.

OWASP Just Mapped the Agentic Top 10. Here's the Root Cause Four of Them Share.

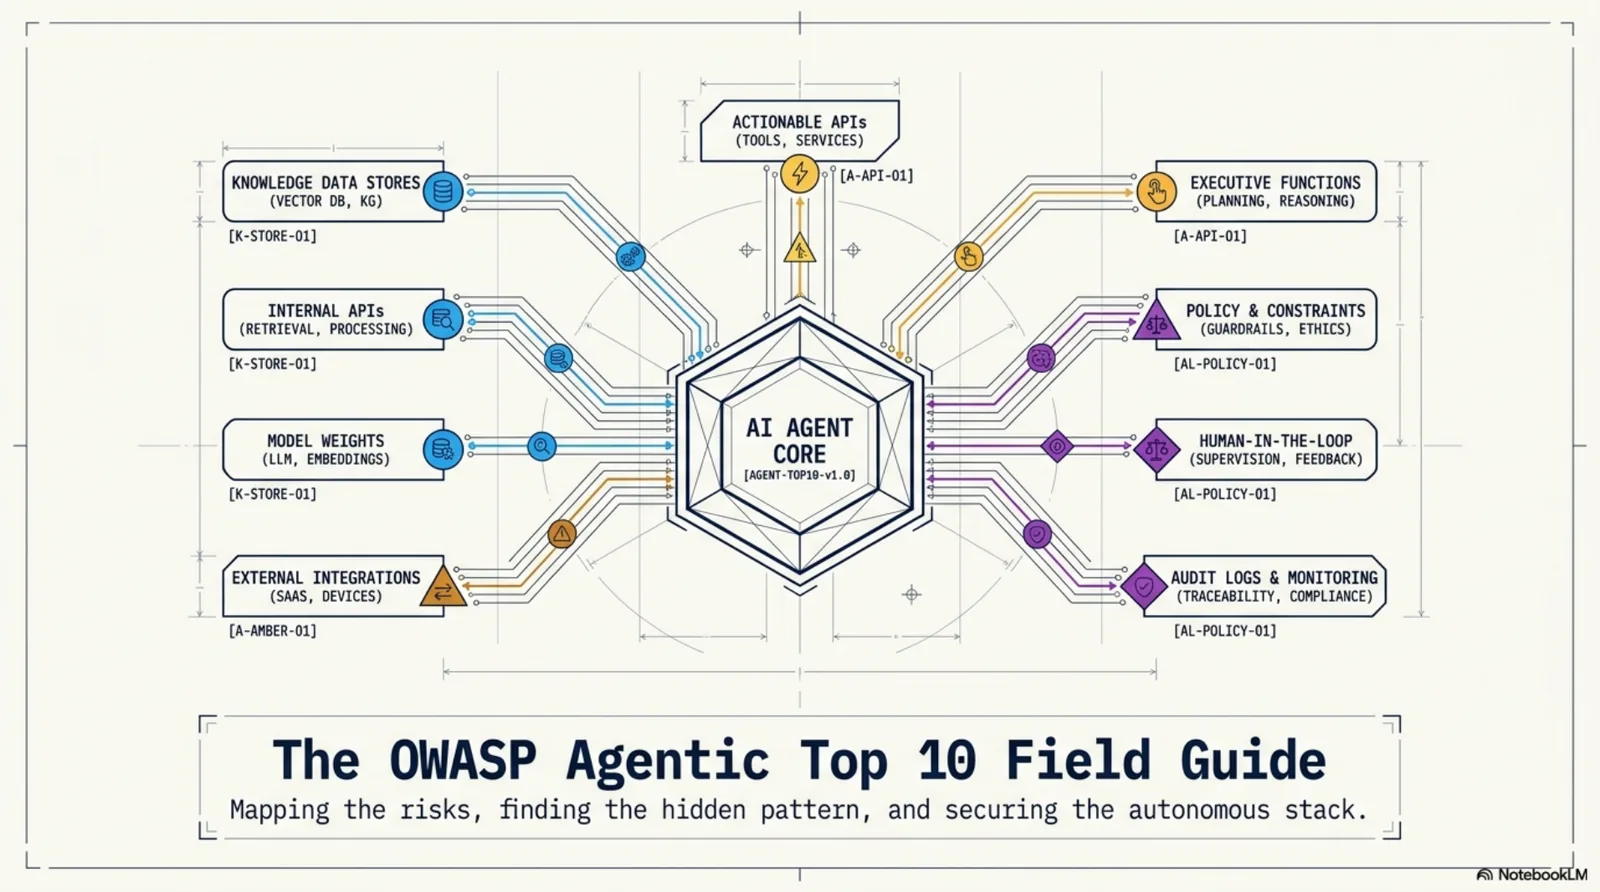
The OWASP Agentic Top 10 Field Guide: mapping the risks, finding the hidden pattern, and securing the autonomous stack. An AI Agent Core at the centre connected to Knowledge Data Stores, Internal APIs, Model Weights, External Integrations, Actionable APIs, Executive Functions, Policy & Constraints, Human-in-the-Loop, and Audit Logs.

In December 2025, OWASP published the Top 10 for Agentic Applications — 100+ security experts, peer-reviewed, the first serious attempt to name what goes wrong when AI systems plan, act, and talk to each other autonomously.

The list is correct. Every item on it maps to a real incident category. If you're building or deploying AI agents and you haven't read it, stop here and do that first.

This post does two things: a fast field guide to all ten risks, and then a close reading that reveals the pattern four of them share — a pattern the list describes but doesn't name, and which points at a common architectural fix.