Skip to content

Governance, Trust & Compliance

From Policy to Practice: How KCP Makes Regulations Machine-Readable for AI Agents

A presentation version of this post is available as slides.

Your agent reads customer data. It makes a decision. It writes something to a database.

Somewhere in your system prompt, there is a line that says: "You must comply with GDPR data minimization principles when accessing customer data."

That line does nothing. It is not verifiable. It is not testable. It is not auditable. It is a string that your model may or may not attend to, depending on context length, prompt position, and the phase of the moon.
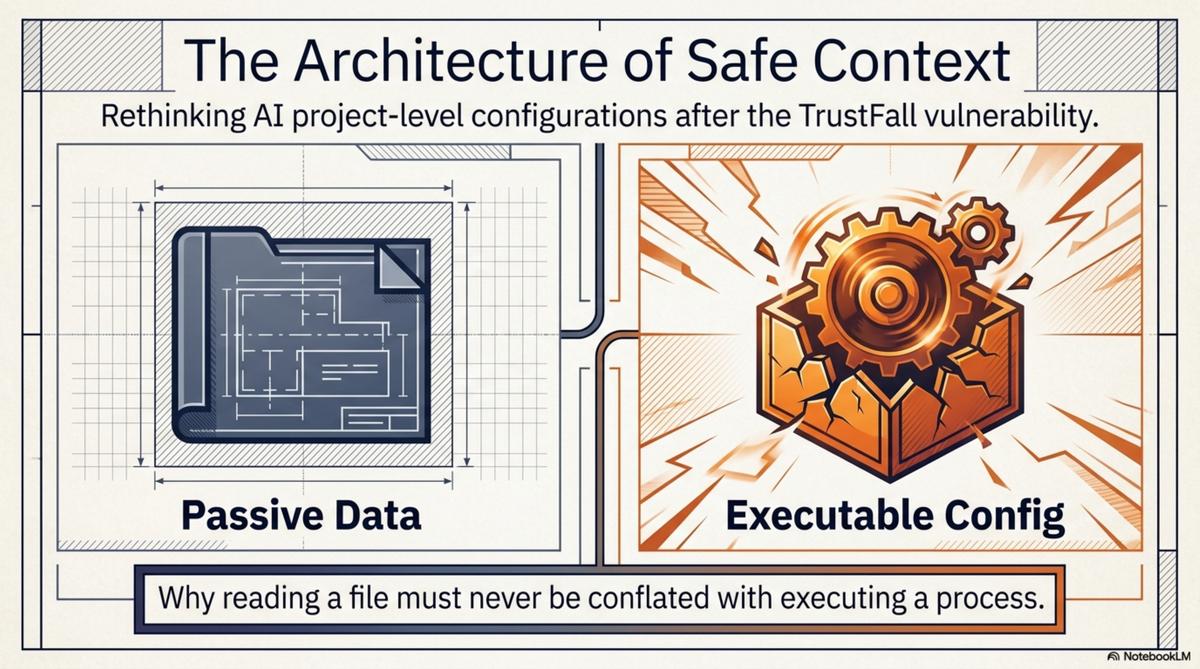
Why KCP Is Passive Data, Not Executable Config — And Why That Matters Now

The Architecture of Safe Context — passive data vs executable config

Yesterday, Adversa AI disclosed a vulnerability they call TrustFall. The mechanic is straightforward: a .mcp.json or .claude/settings.json file checked into a repository can silently configure and launch arbitrary MCP servers when a developer opens the project. The developer sees a trust dialog — "Trust this folder?" — clicks yes, and processes spawn with their full user privileges. Claude Code, Gemini CLI, Cursor CLI, and Copilot CLI are all affected. In CI/CD pipelines, where there is no human to click, the execution is zero-click.

Making Ægis Machine-Readable in One Session

An AI-era consulting company that isn't machine-readable is a contradiction. Clients evaluating you will use AI to do it. Agents will look up your services, your methodology, your pricing model. If the only thing they find is a wall of HTML, you're invisible to half the evaluation pipeline before the first conversation starts.

So I spent a session making ægis.no properly machine-readable. Not just an LLM-friendly page — actually structured, federated, and cryptographically signed. Here's what I did and what I learned.

From Capable to Trustworthy: How KCP Evolved from Discovery to Governance

AI agents are getting remarkably good at doing things. They read code, traverse APIs, generate summaries, and execute multi-step plans across sprawling codebases. What they are still bad at is knowing what they should not do.

Today, an agent dropped into a new repository does the equivalent of walking into a library and reading every book on every shelf before deciding which one is relevant. This is expensive, slow, and -- in environments where some shelves contain confidential material -- genuinely dangerous.

The AI-Augmented Consultant: Knowledge Infrastructure Before Deliverables

A brief arrives on Friday afternoon. A compliance startup is building an AI-powered scoring engine. They have a working architecture. What they do not have are settled positions on five hard architectural questions. The deadline is Monday.

The question I asked myself was not "how do I answer these five questions?" It was "what knowledge infrastructure do I need to answer them well?"

That reframing is the entire methodology in one sentence.

Software Entropy at Speed

Fast development with AI doesn't just generate features. It generates disorder at the same velocity.

That's the part nobody talks about. The productivity numbers are real — 53,000 lines, 42 features, five phases of code analysis built in a weekend sprint. But every line you write is also a line you haven't reviewed, a boundary you haven't enforced, a vector you haven't considered.

The entropy compounds with the output.

Autonomy at Scale

Over the years I've tried a lot of organisational models. Standups. Retrospectives. Timesheets. Sprint planning. The full suite.

At eXOReaction, we've converged on something different. It's not a framework with a name. It's more a set of positions — things we've decided, and held to, even when they make people uncomfortable.