Multi-agent systems need two kinds of identity. The first answers "who is this agent and how do I call it." The second answers "what knowledge does this agent have and who is allowed to see each piece of it." Google's A2A protocol handles the first. KCP handles the second. They are not competitors. They are different layers of the same stack.
This post started as that explanation. Then, the same day it was published, we built four simulators and 150 adversarial tests against the spec. The tests found 8 concrete gaps. Those gaps are now driving KCP v0.7. The full story follows.
Most teams using AI for development have settled on a workflow that looks roughly like this: write a detailed specification, feed it to the agent, review the output, iterate. It is disciplined. It is responsible. It works. And after six months of watching it in practice, I believe it has a structural limitation that becomes more expensive the longer you use it.
The limitation is not quality. Spec-driven development produces good output. The limitation is that every session starts from zero. The spec carries the knowledge. The agent carries nothing.
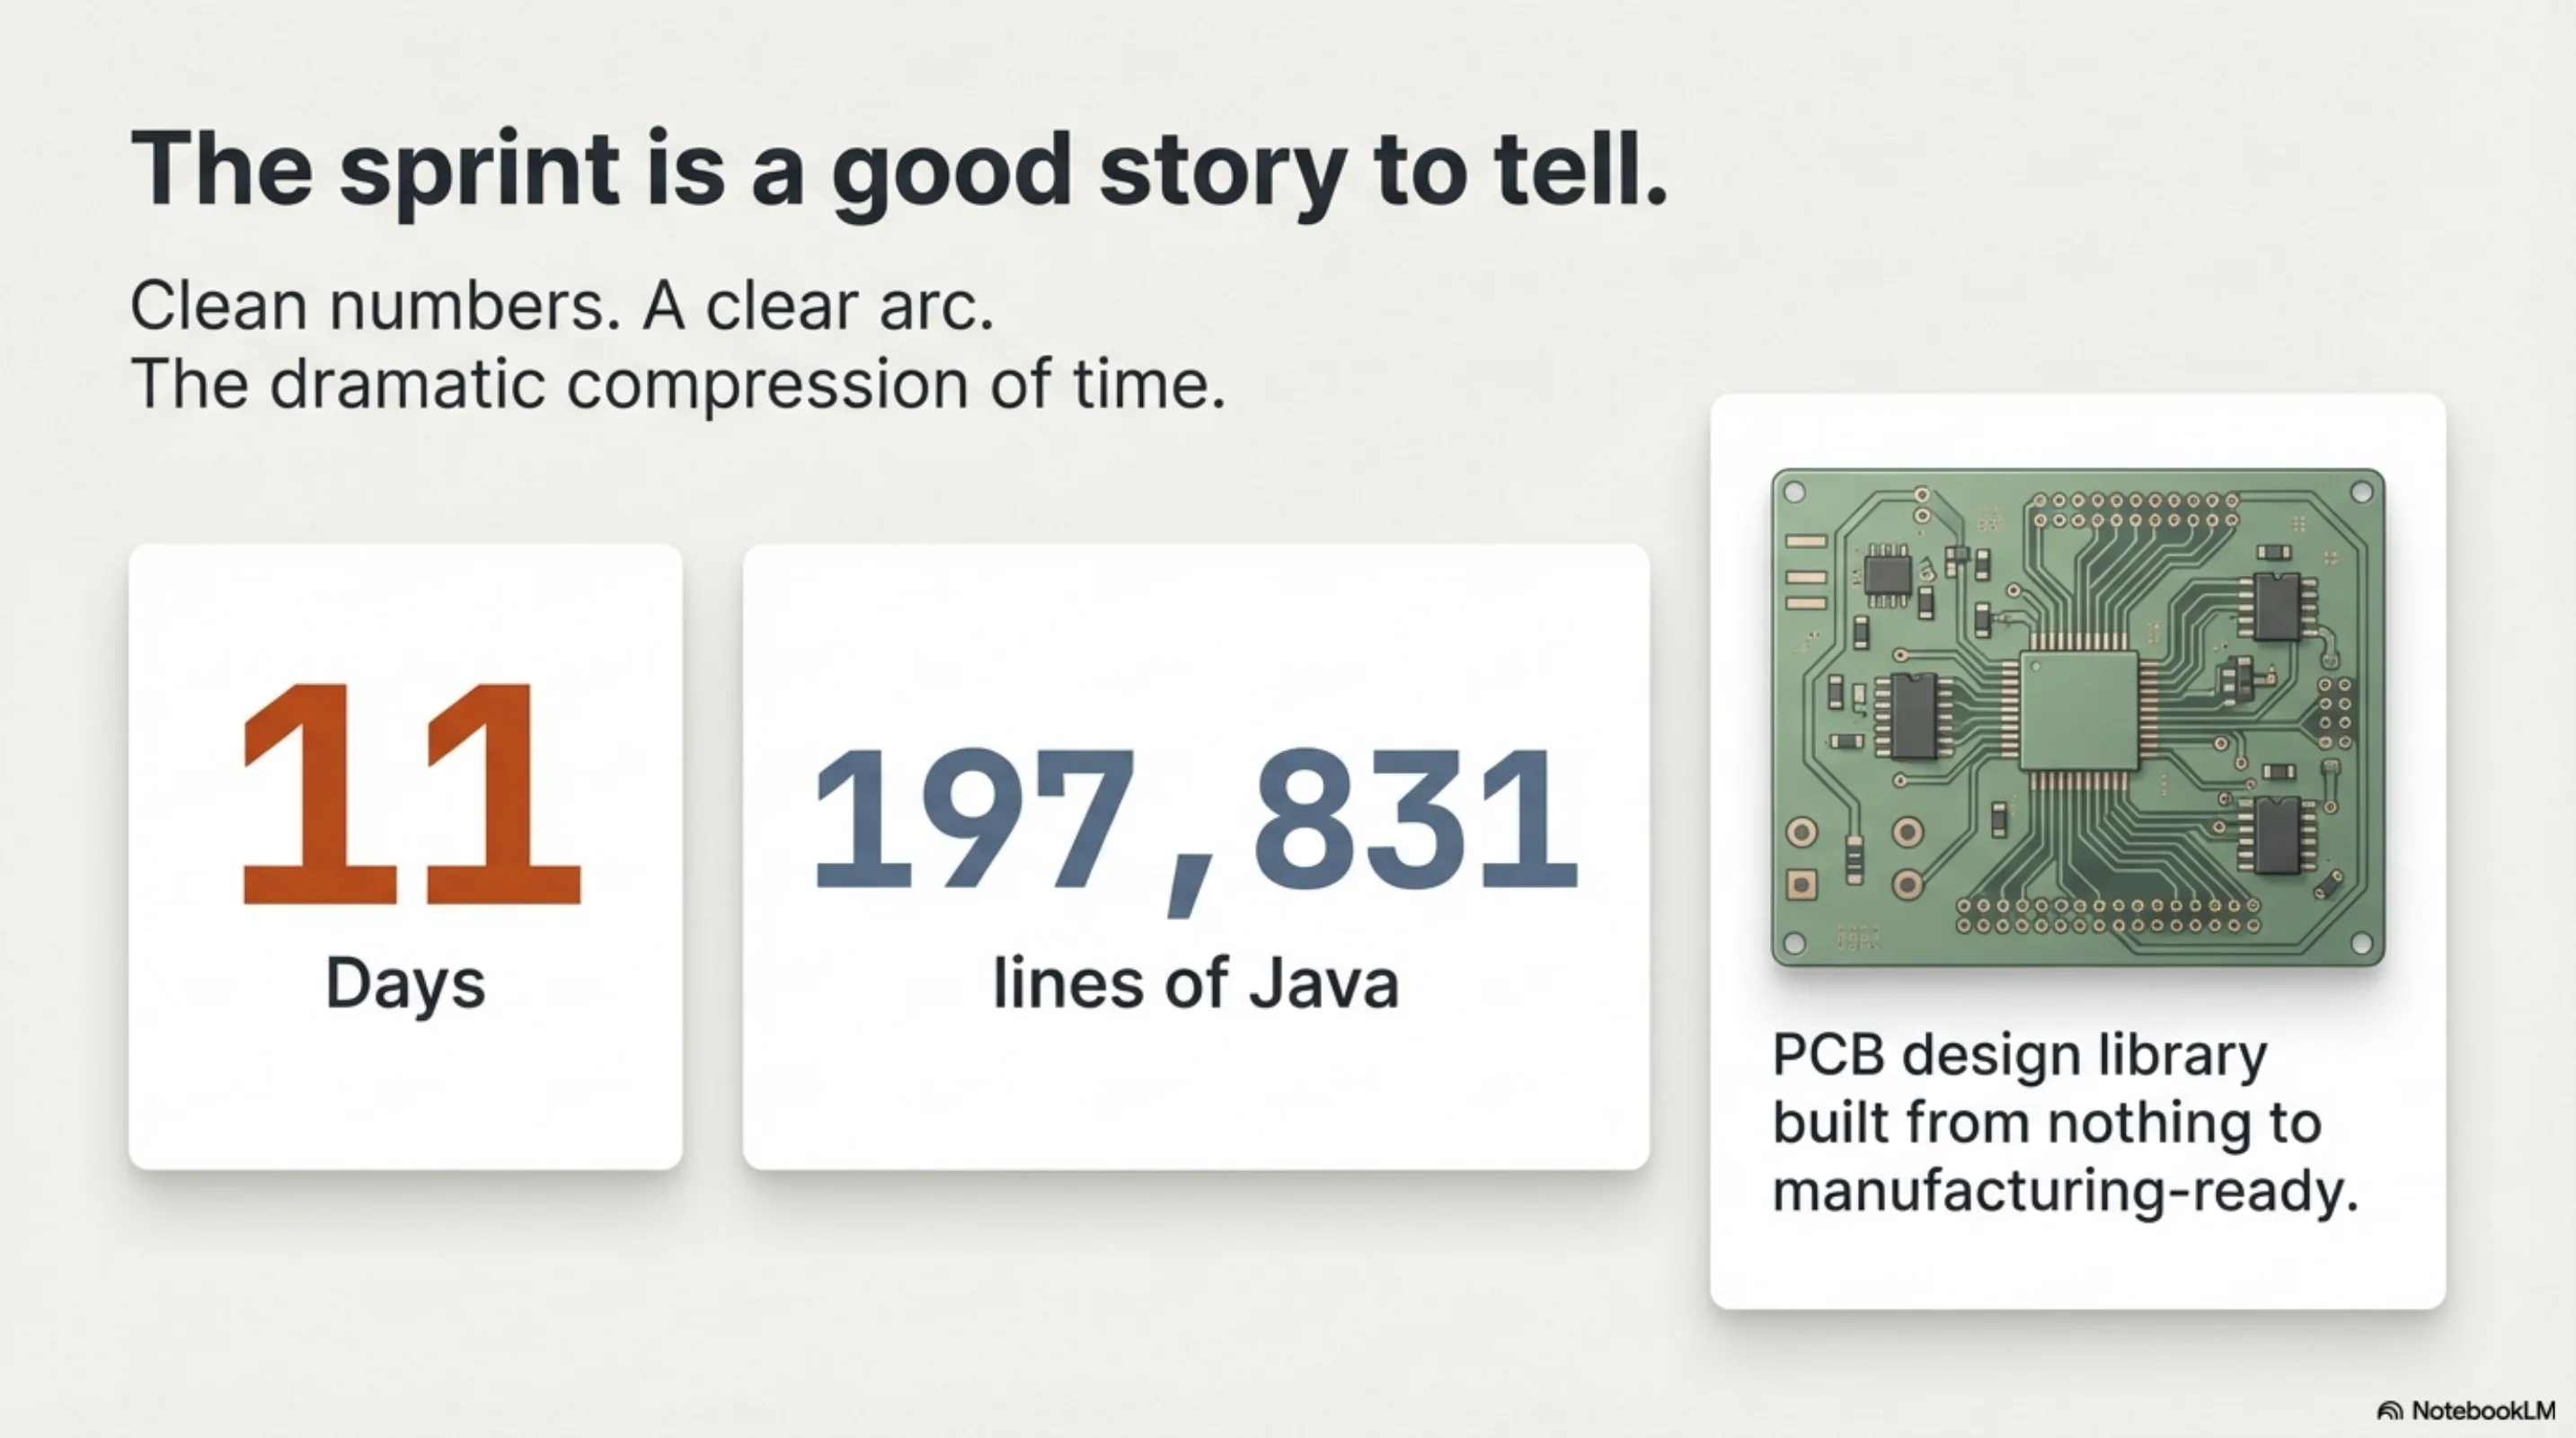
Eleven days. 197,831 lines of Java. A PCB design library built from nothing to manufacturing-ready. Clean numbers, clear arc, dramatic compression of time.
That was January 27. Six weeks ago.
Nobody asked what happened after. Which is the point.
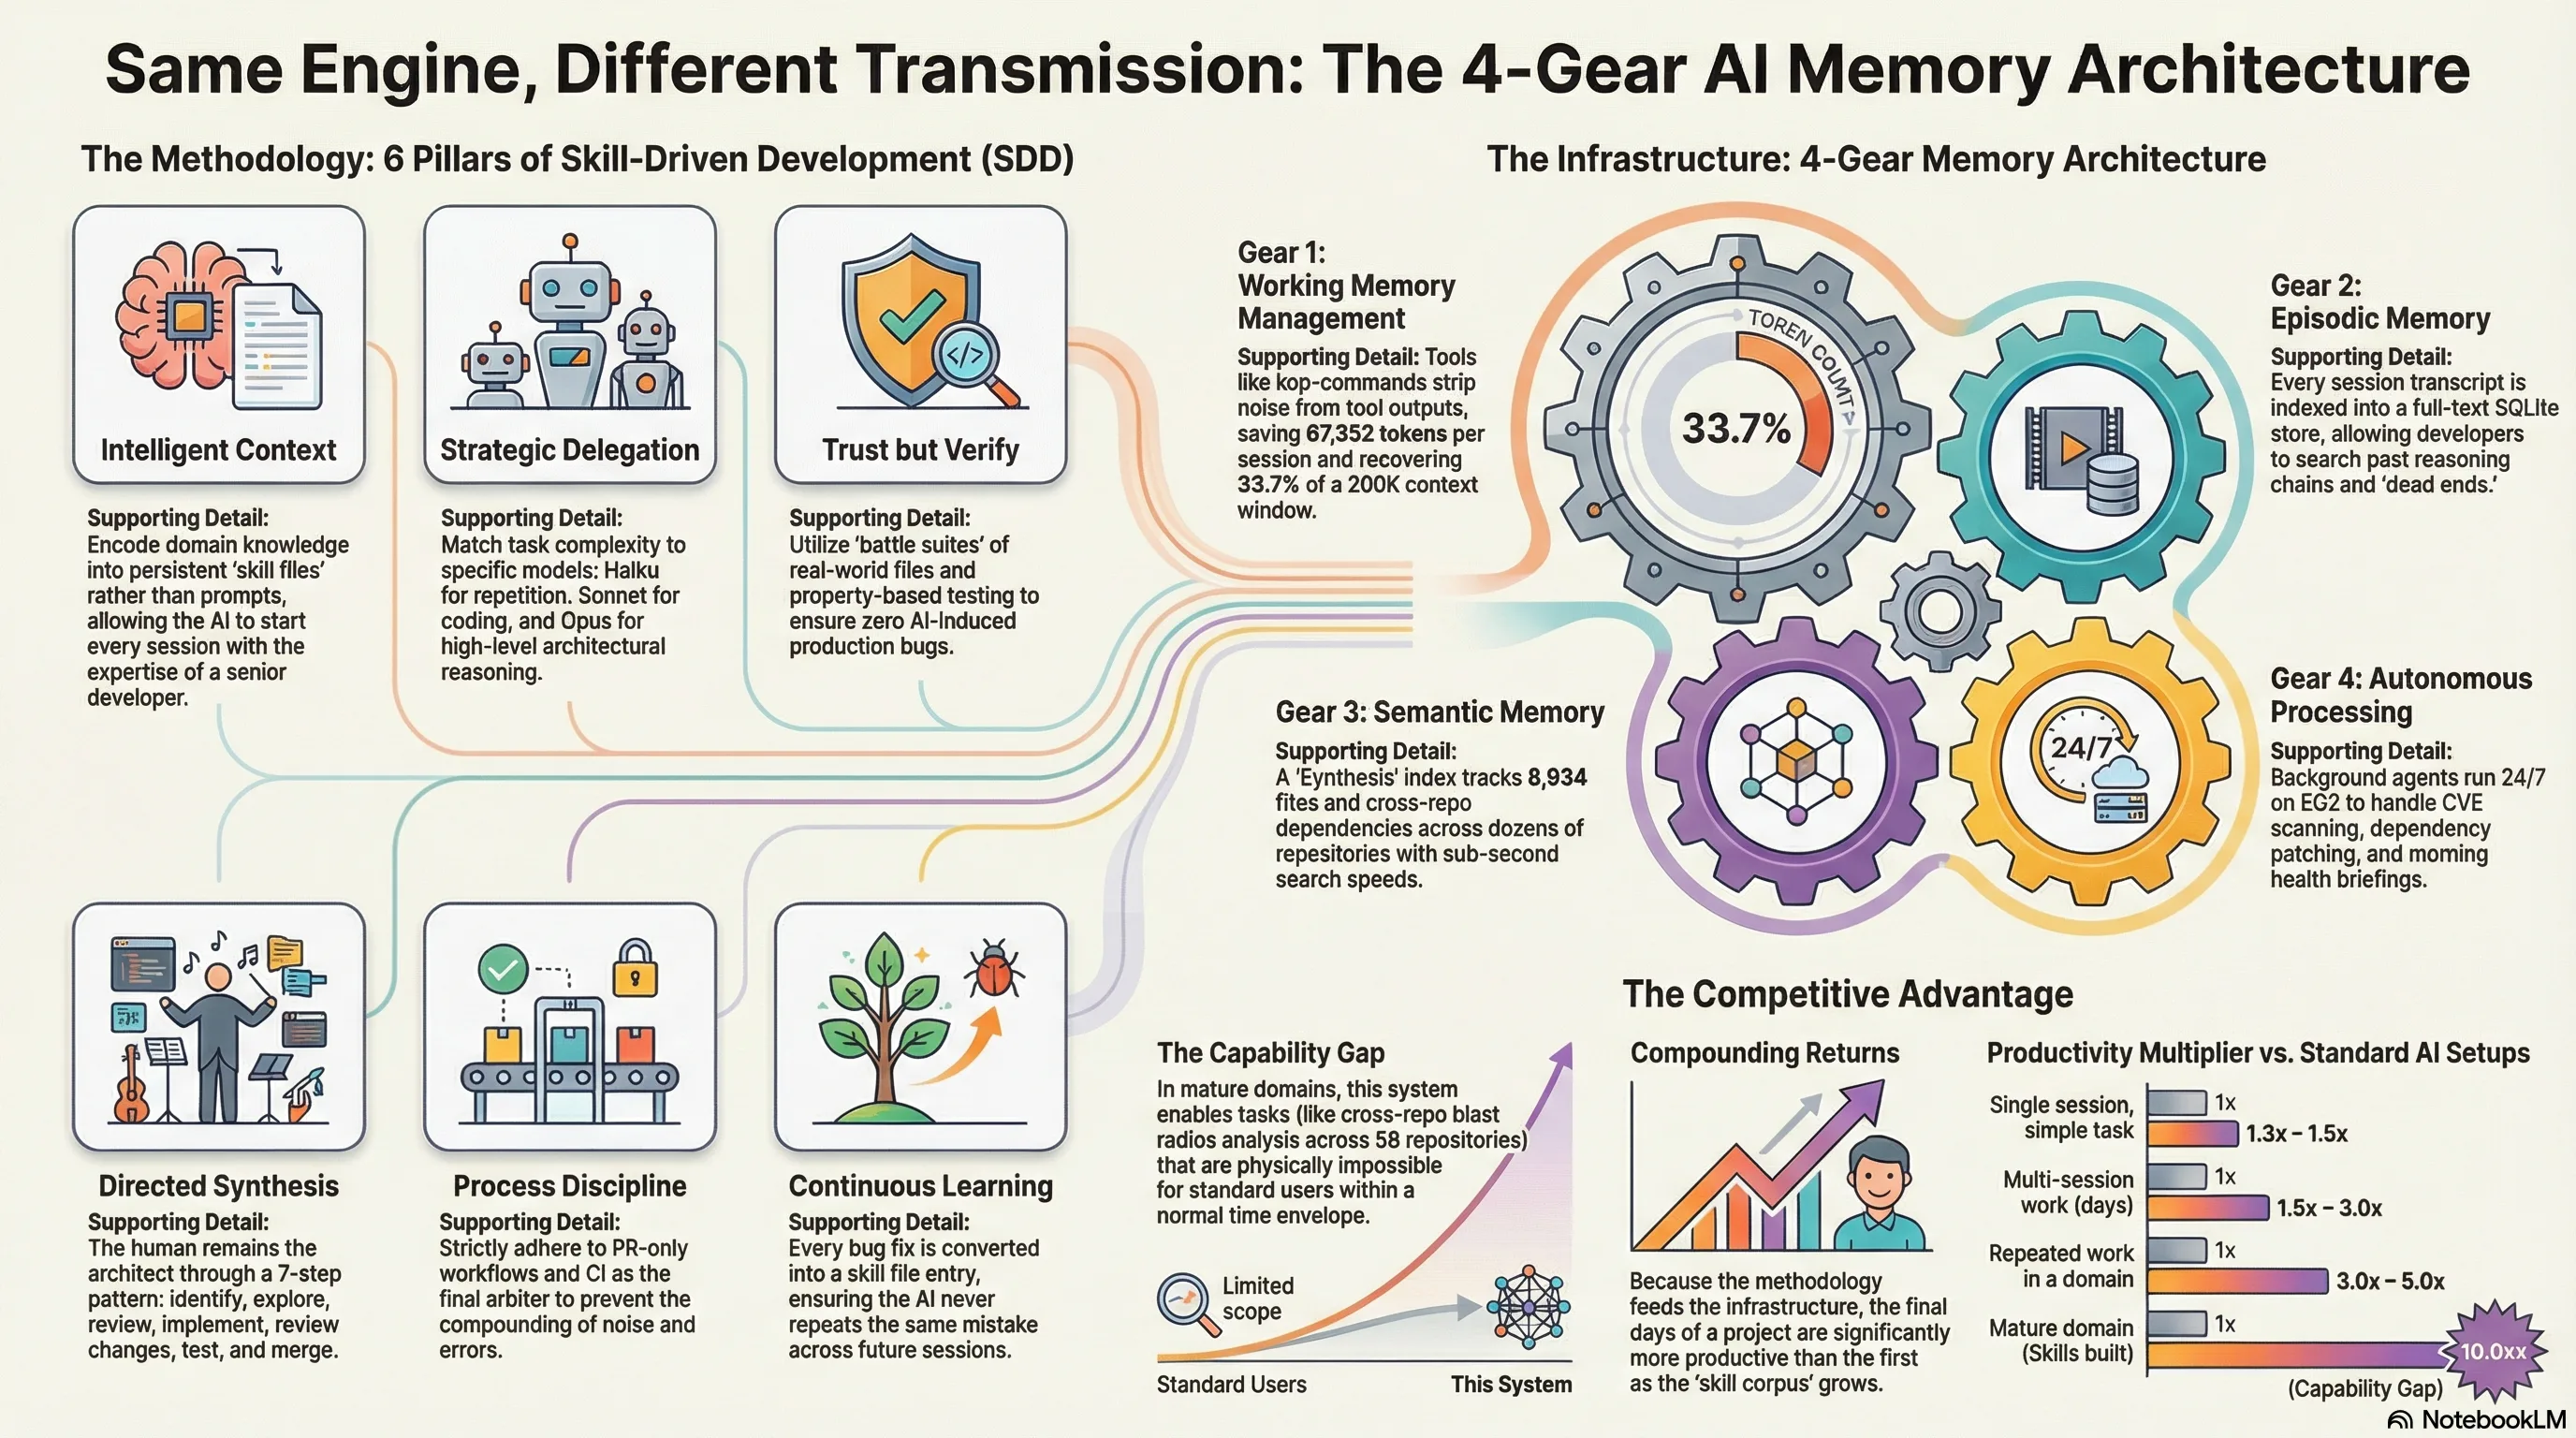
Most AI productivity discussion asks the wrong question. "How much faster?" assumes the difference is speed. It is not. Two developers using the same model, the same IDE integration, the same subscription tier -- one of them starts every session cold and the other does not. The gap between them is not the engine. It is the transmission. But the transmission alone is not the full story either. There is a third variable: how the driver was trained.
Every Claude Code session starts the same way. The context window is empty. The agent
has no recollection of what it did yesterday, which files it touched last week, or how
it solved a similar problem three sessions ago. Each session is day one.
That is not a limitation of the model. It is a missing infrastructure layer.
Today we are releasing kcp-memory v0.1.0: a standalone Java daemon that indexes
~/.claude/projects/**/*.jsonl session transcripts into a local SQLite database with
FTS5 full-text search. Ask it "what was I working on last week?" and it answers in
milliseconds.
Update (same day — v0.2.0): kcp-memory now ships with tool-level granularity.
kcp-commands v0.9.0 writes every Bash tool call to
~/.kcp/events.jsonl; kcp-memory ingests that stream and makes individual commands
searchable via kcp-memory events search. Session-level and tool-level memory in one
daemon, one database, zero additional dependencies.
Update (same day — v0.3.0): kcp-memory now ships as an MCP server. Run
java -jar ~/.kcp/kcp-memory-daemon.jar mcp — registered in mcpServers in
~/.claude/settings.json — and Claude Code can call kcp_memory_search,
kcp_memory_events_search, kcp_memory_list, and kcp_memory_stats inline during a
session, without leaving the context window.
Update (same day — v0.4.0): Two new MCP tools close the remaining gaps.
kcp_memory_session_detail(session_id) returns full session content — user messages,
files touched, tools used — completing the search → read flow. kcp_memory_project_context()
reads PWD from the process environment and returns the last 5 sessions and 20 tool events
for the current project, with no query needed. Call it at the start of every session and
Claude immediately knows what it was doing here last time.
kcp-commands recovers 33% of Claude Code's context window
by intercepting Bash tool calls. Today we are extending that same principle to
OpenCode — the 114K-star TypeScript alternative to
Claude Code.
The result is opencode-kcp-plugin: a plugin
that injects a knowledge.yaml knowledge map into every OpenCode session and annotates file
search results with intent descriptions. The mechanism is different from kcp-commands, and the
target is different, but the underlying idea is identical: give the agent a map so it does not
have to rediscover the territory on every session.
Every session starts from zero. The agent cannot remember the decision it helped you make last Tuesday, the bug it spent three hours debugging last week, or the architectural pattern you established last month. This is not a model capability problem. It is a memory architecture problem — and it has a tractable solution.
A brief arrives on Friday afternoon. A compliance startup is building an AI-powered scoring engine. They have a working architecture. What they do not have are settled positions on five hard architectural questions. The deadline is Monday.
The question I asked myself was not "how do I answer these five questions?" It was "what knowledge infrastructure do I need to answer them well?"
That reframing is the entire methodology in one sentence.