A production scar is not a bug you fixed. It is a category of failure that was surprising enough to cause architectural change — something you now defend against mechanically because trusting the model to avoid it didn't work.
Santander AI Lab called their open-source release "battle-tested solutions from production scars." ExoCortex has its own. Six of them. Each one left a hook file on disk that implements the lesson. This post documents what failed, why prose instructions couldn't fix it, and what the mechanical fix looks like.
You're building a product. It handles personal data. You've added an AI assistant that helps customers understand their compliance obligations. Good instinct, bad outcome -- because the assistant will tell a customer their processing of health data is fine since they have consent. It will say this fluently, with bullet points, citing GDPR Article 6. It will be wrong.
Article 9 requires a separate legal basis for special category data. Consent under Article 9(2)(a) must be explicit -- a higher bar than the regular consent in Article 6(1)(a). The agent doesn't know this, because it has no authoritative source for it. It's working from training data where "consent" is the answer to most GDPR questions.
This post shows the architecture that fixes that. Six layers, each solving a distinct failure mode, each buildable independently. By the end you'll have a pattern for turning any regulation into machine-readable knowledge, wiring it into an agent, and proving the agent's answers are correct.
On June 12, 2026, Google Cloud published the Open Knowledge Format (OKF). I read it the same day. My first reaction was: this is good news. My second reaction was: they stopped exactly where it gets hard.
Practitioner notes on shipping a feature that was already a no-op, in two different ways.
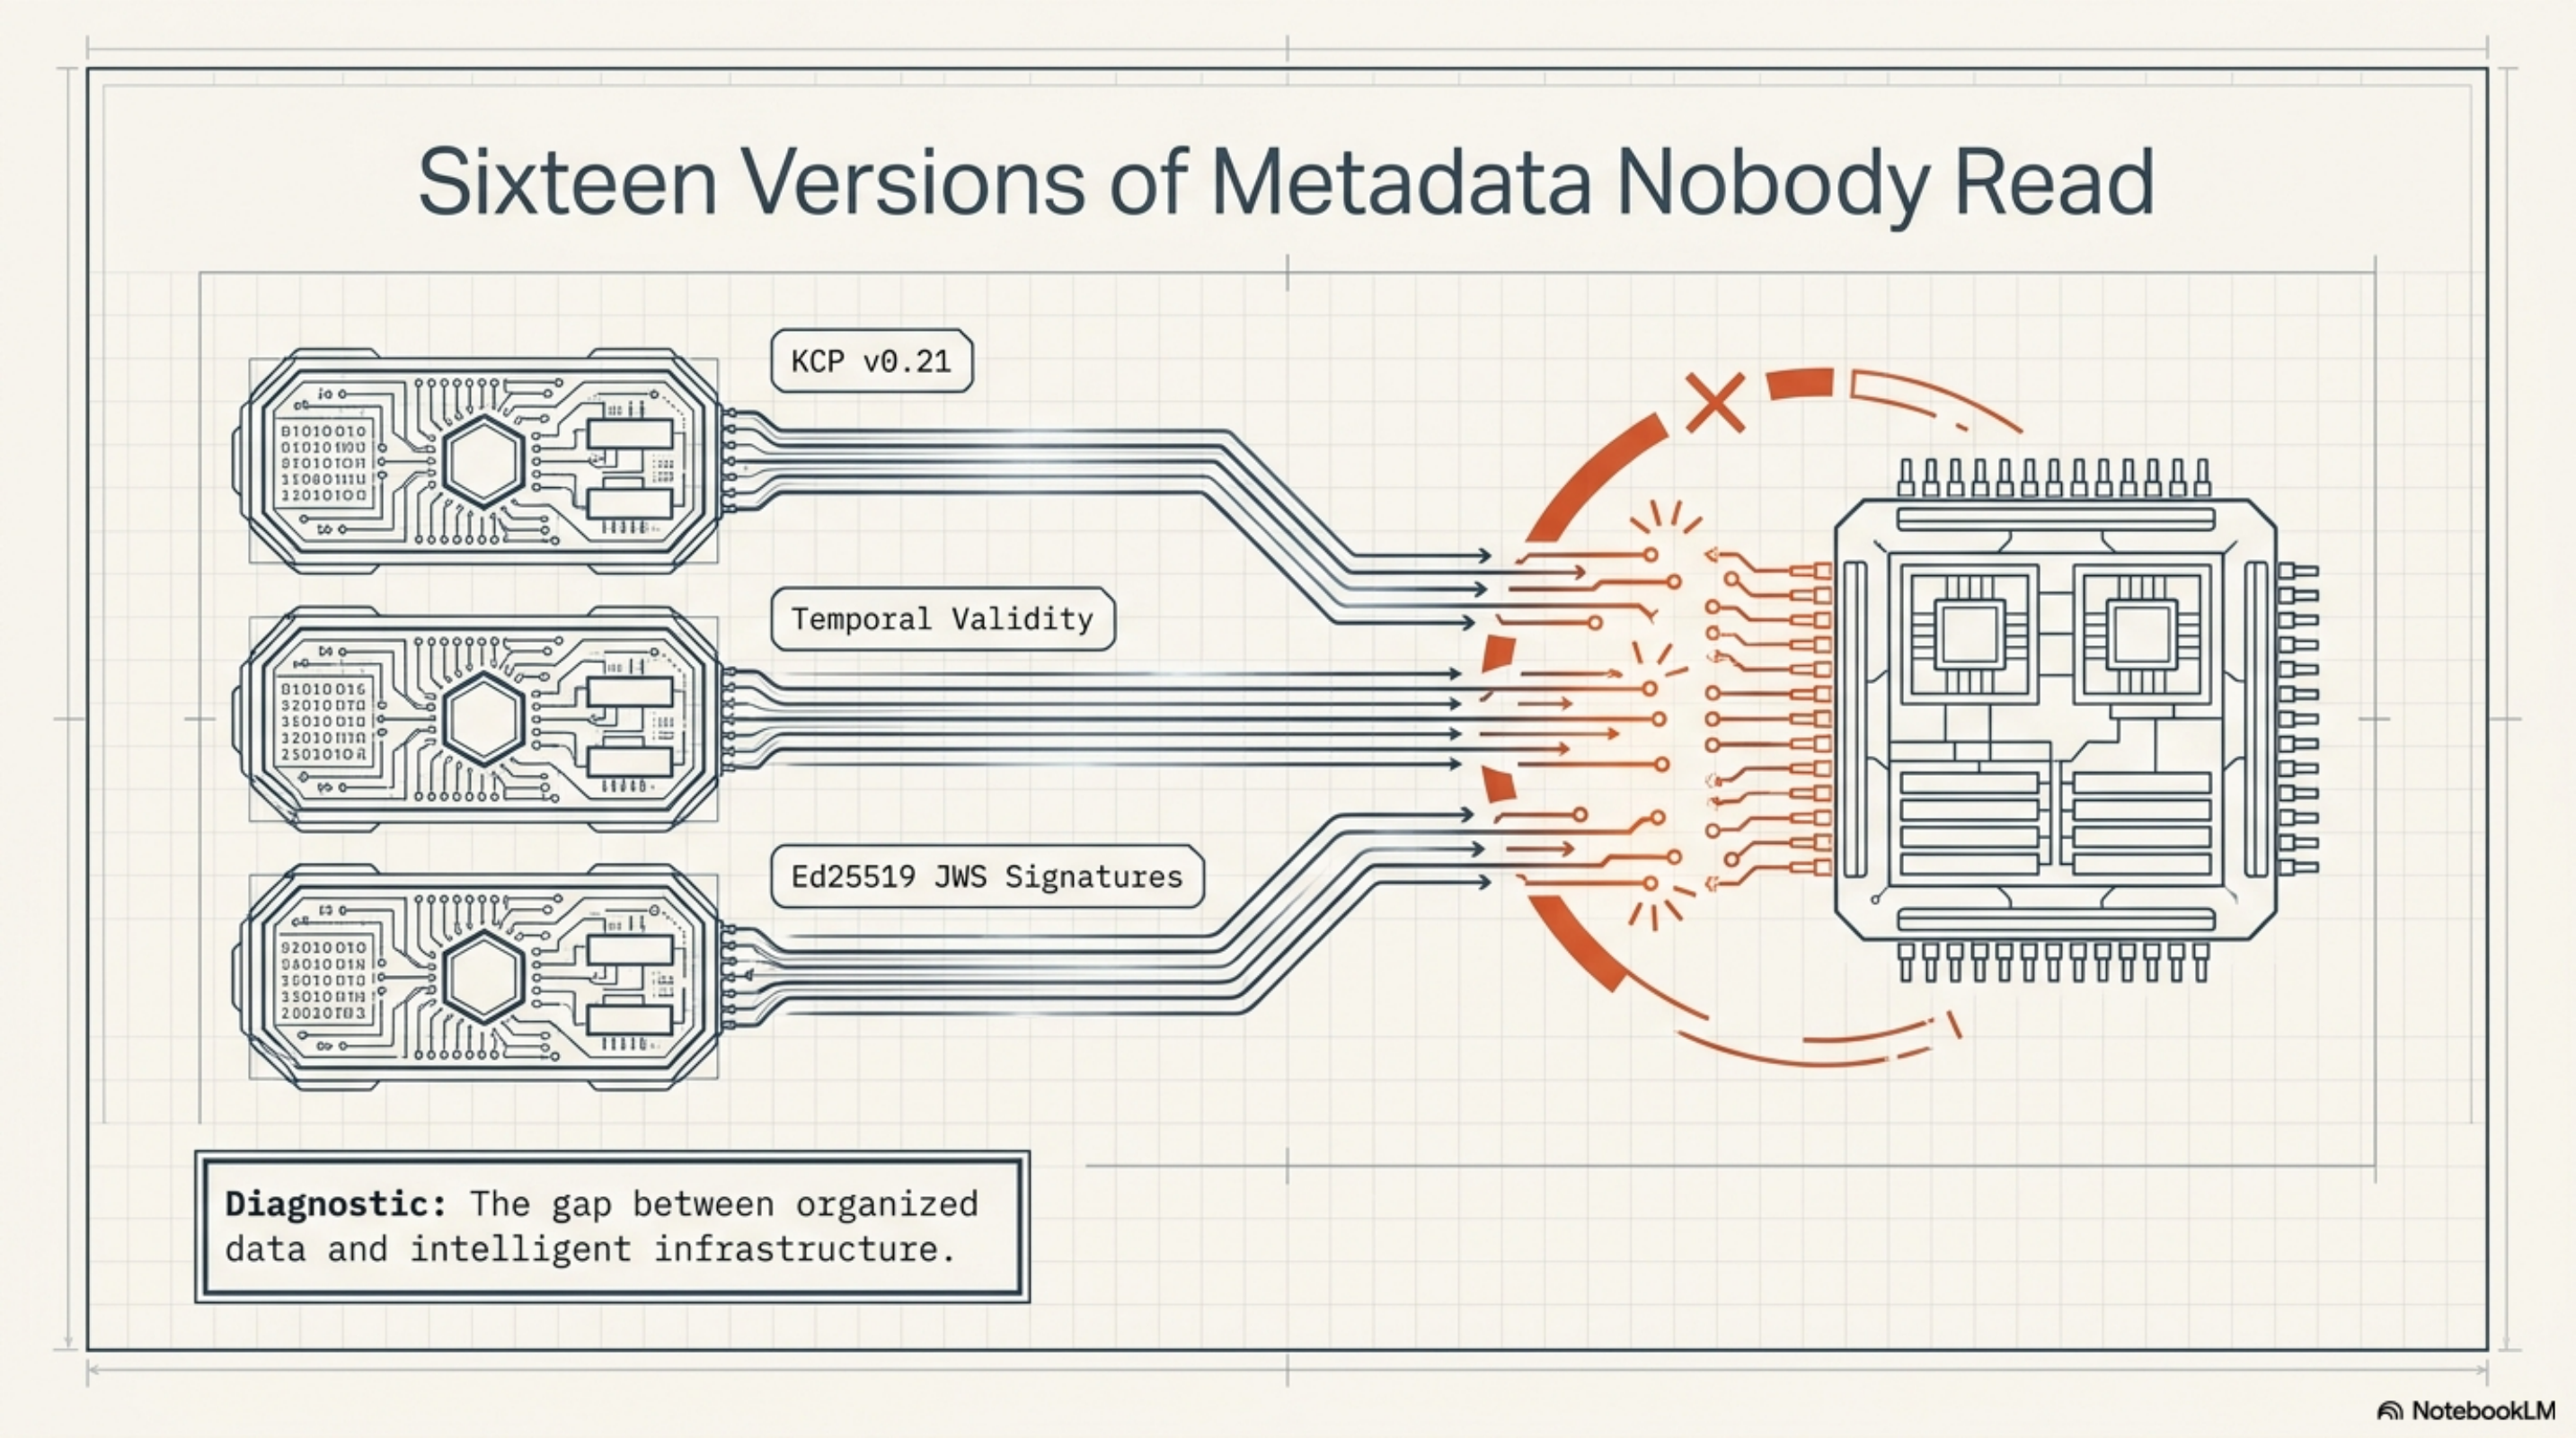
The Mynder regulatory knowledge base has 63 fragment manifests covering 101 units of EU regulation — GDPR, NIS2, the EU AI Act, DORA, Norwegian and Swedish data protection law. Every unit carries temporal validity (valid_from, valid_until, superseded_by), per-unit content hashes (sha256), not_for audience filtering, content structure declarations, and Ed25519 JWS signatures. All of it declared in KCP v0.21.
Synthesis — the workspace intelligence tool that indexes and searches this corpus — was reading it at v0.5 feature level.
Sixteen spec versions of metadata, sitting in the files, being dutifully indexed and completely ignored by the tool whose job was to understand them. The corpus was "searchable" but not "knowledge-aware." You could find GDPR articles by keyword. You could not ask what was in effect in 2022 and get a time-correct answer.
This morning I spent three hours on regulatory knowledge infrastructure. 63 fragment manifests across Arbeidsmiljøloven, GDPR, NIS2, DORA, AI Act, NSM Grunnprinsipper, Dutch financial supervision law. Fixed a scope validation bug across 30+ files. Extracted 38 Dutch obligation units from inline YAML to standalone navigable text. Everything passing kcp validate by lunch.
None of it would normally get published. Too narrow. Too technical. No audience in the traditional sense — a compliance engineer isn't subscribing to this blog, and a developer evaluating KCP isn't refreshing the RSS feed waiting for fragment extraction patterns.
That instinct is correct. If you're writing for humans, ruthless editing is the right move. Cut the scope validation bug. Keep the summary. Optimize for skimmability, because human reading bandwidth is fixed and attention is scarce.
The instinct is right. The assumption about who's reading has become incomplete.
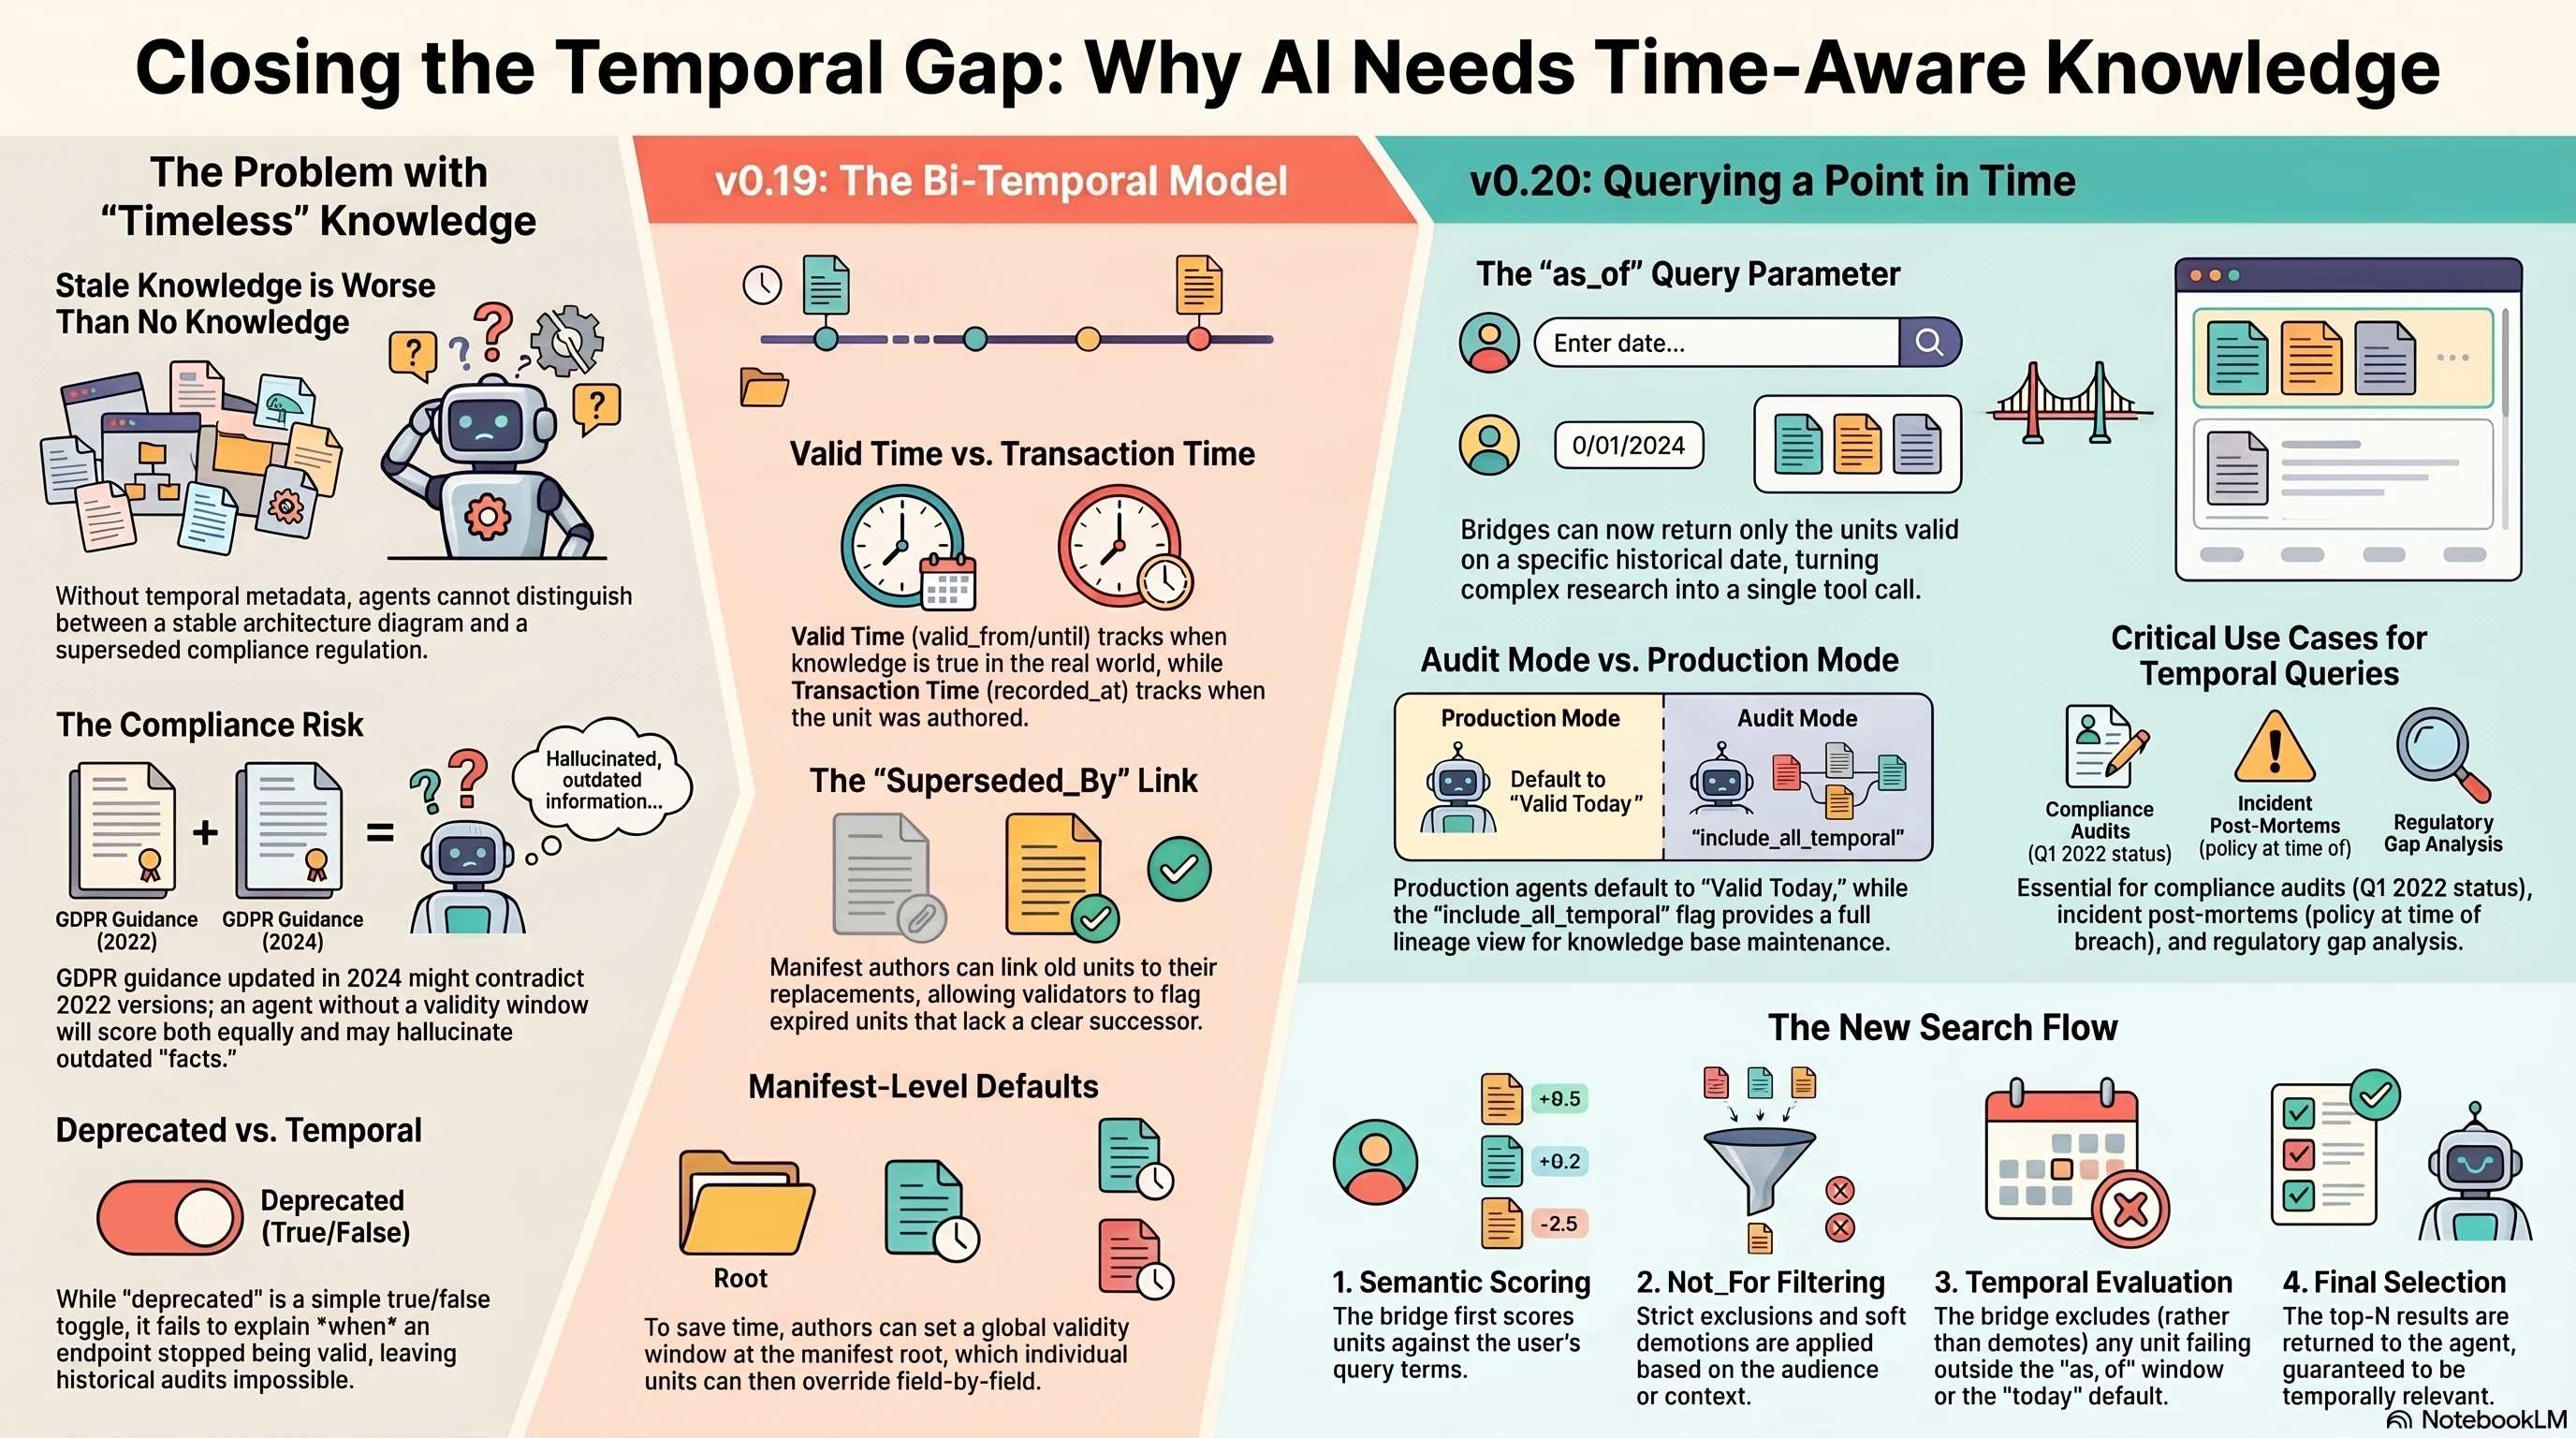
The previous post ended with a list of gaps still visible after v0.18: federated trust delegation, transport integrity, digest cost budgets. The one I left off the list, because it was already in progress, was time.
Not performance. Not latency. Actual calendar time — the question that turns out to matter enormously for knowledge that agents load into context: when is this unit valid?
v0.19 and v0.20 answer that question. v0.19 lets manifest authors declare temporal validity. v0.20 lets agents query against it.
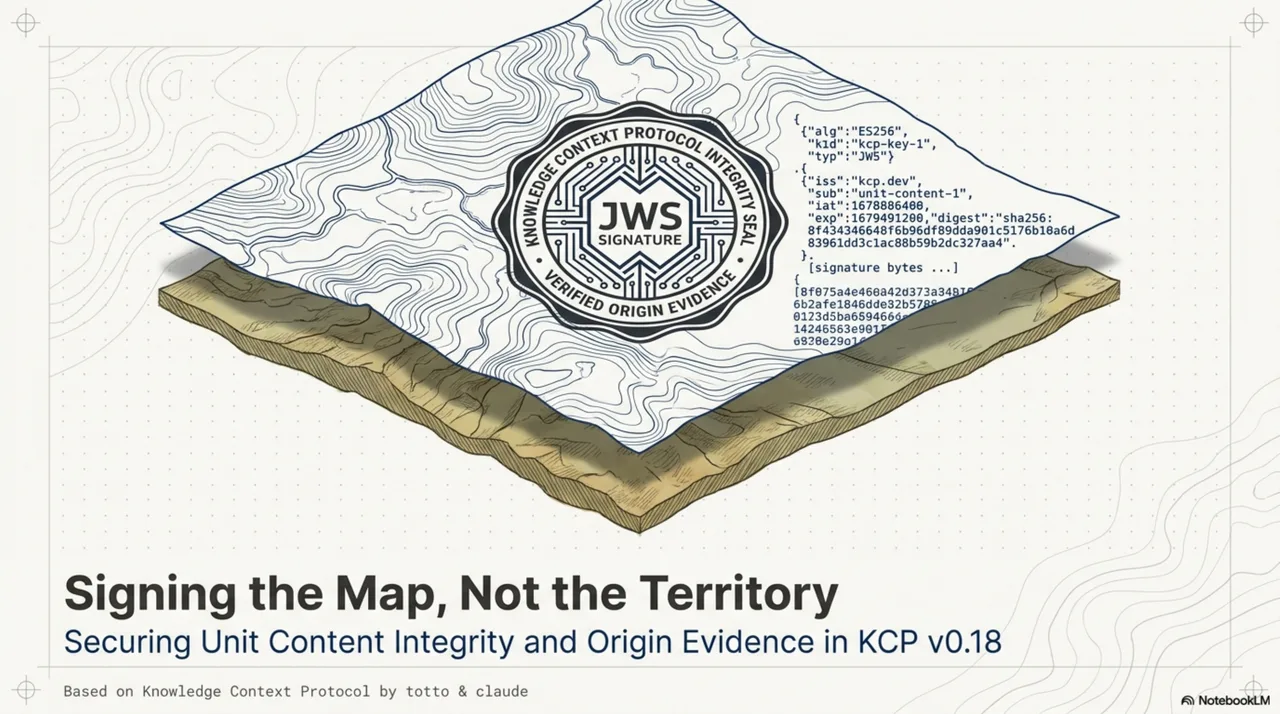
The previous post showed how KCP v0.16 gives manifests a trust model: cryptographic signing, trust tiers, a render pipeline that fails closed. The signature covers the manifest -- the YAML bytes that describe your knowledge units. It does not cover the files those units point to. The signature says "this map is authentic." It says nothing about the territory.
That gap has a name: T9, the manifest relocation attack. v0.18 closes it.
It started with a question no one expected to be hard.
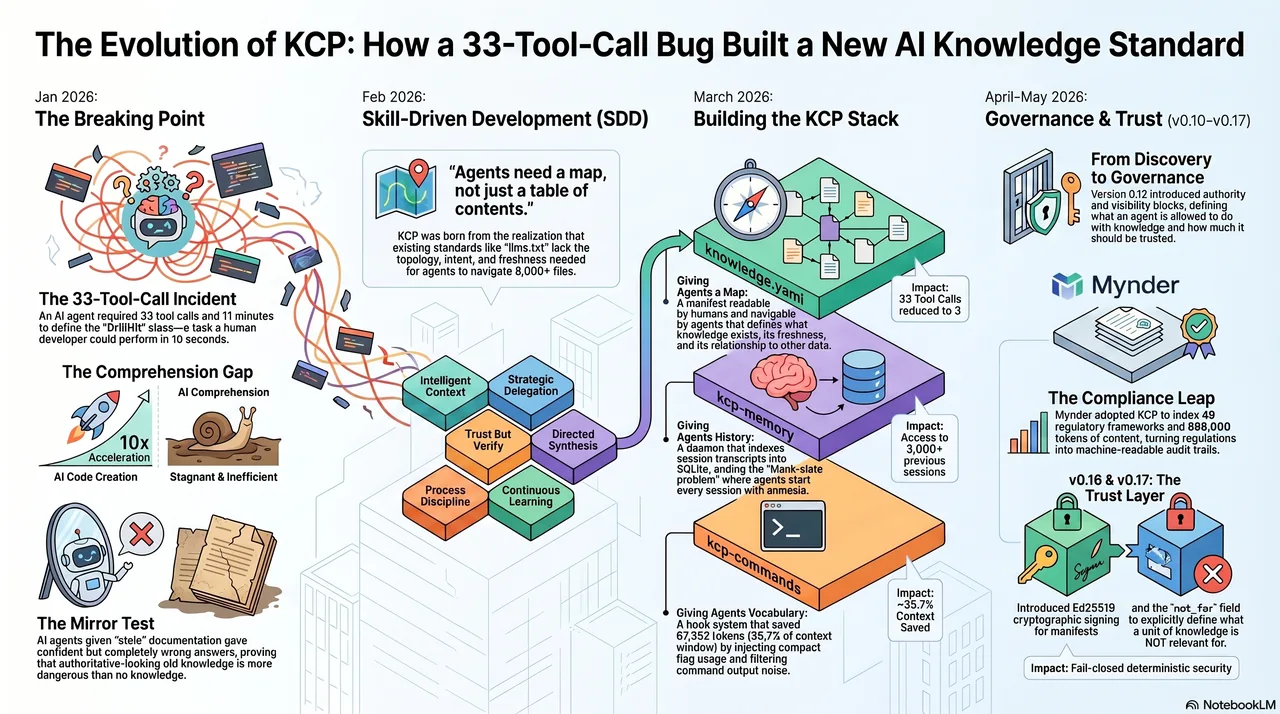
Day seven of the lib-pcb build. January 2026. A single developer, eleven days to produce what the industry does in ten to eighteen months. The AI was generating code at a pace that defied every estimate. Features that should take a week arrived in hours. The skill library -- YAML files encoding project-specific context for Claude Code -- had grown to over forty entries. Everything was working.
And then everything stopped.
"What fields does the DrillHit class have?"
The AI did not know. The class had been written four days earlier. It was central to the entire parsing architecture. It had been discussed in multiple sessions. But the context was gone -- fresh session, blank slate. The AI started searching. Grep for the class name. Read the file. Follow the imports. Check the parent class. Read that file. Check the serializer. Follow another import. Back to grep. Thirty-three tool calls to answer a question that any developer on the project for a week could answer in ten seconds.
Eleven minutes. For one question.
That was the moment something broke open. Not the code -- the assumption underneath it. The assumption that making AI faster at creating code was sufficient. Creation had been accelerated by an order of magnitude. Comprehension had not moved at all.
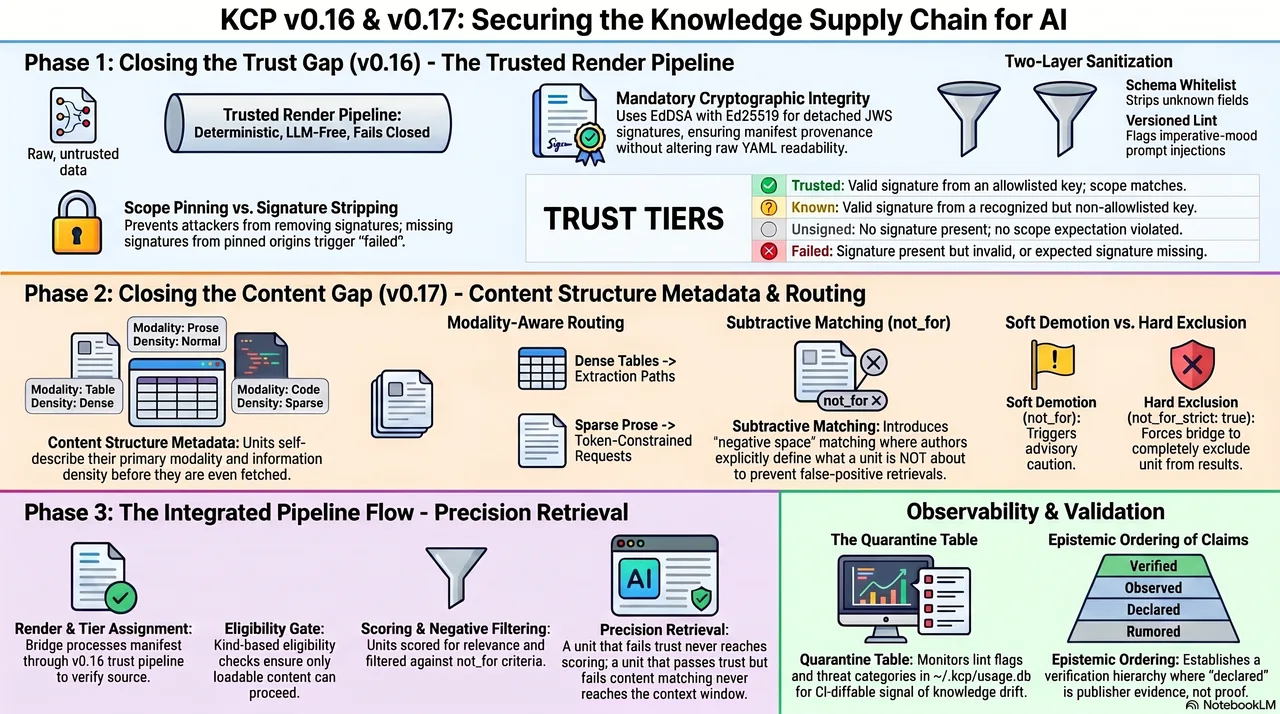
When a compliance agent evaluates a supplier against NIS2 Article 21, it needs two things: the supplier's security documentation to evaluate, and the regulation to evaluate it against. KCP, as described in the previous post, gives the supplier documentation a shape. The evaluation result gets a shape. But the regulation itself -- the specific requirements of Article 21(2), the interpretive guidance from ENISA, the national implementation notes -- lives where it has always lived: as prose in the system prompt.
That worked when agents consumed knowledge from a single, trusted source. It does not work when your agent pulls context from four federated manifests across two organisations, one of which was generated by an automated crawl three weeks ago. The question is no longer "does this knowledge have a shape?" It is: "can I trust this knowledge, and is it even the right content for what I need?"
KCP v0.16 and v0.17 answer those two questions. v0.16 introduces a trust model -- cryptographic signing, trust tiers, a render pipeline that fails closed. v0.17 introduces a content model -- structural metadata that tells you what a unit contains before you fetch it, and subtractive matching that tells you what it is explicitly not about. Together, they close two gaps that have been open since the beginning of the series.
This post walks through both releases. The examples are concrete. The threat model is explicit. If you are building systems where agents ingest knowledge from sources you do not fully control, this is the machinery that makes that safe.
Practitioner notes on the verification you only do once.
In the previous post I described catching an agent claiming a parser was "fully RFC compliant." I caught it by opening the RFC — four minutes of reading against a parser that handled none of the wildcard support the spec requires.
The tips in that post were about catching such claims. This post is about a better question that took me longer to ask:
Why did the agent never open the RFC?
Not because it couldn't read it. Because the RFC wasn't there. The agent had the parser in its context and the spec in its vibes — a compressed, lossy impression from training data. Asked to compare code against a standard, it compared code against its memory of the genre of that standard. Of course it produced an adjective.
You can audit that failure forever. Or you can change what the agent reasons from.