Skip to content

AI-Augmented Development

Explorative Development

Practitioner notes on engineering as a sequence of experiments — and on who does what in the loop.

Before we wrote the production code for a recent platform feature, we ran a fictional organization through two years of using it.

Twenty-four simulated months of compliance life: onboarding, supplier churn, audits, incidents, people leaving with their knowledge. The simulation produced fifteen architectural findings — wrong assumptions and missing pieces, discovered while every fix was still cheap and no customer existed yet. Sibling simulations took the total to twenty-five. A design meeting on the same material would have produced opinions.

That run is the clearest recent example of how I've worked for years, and of what I've started calling the approach out loud: explorative development. An idea becomes a hypothesis. The hypothesis becomes the cheapest implementation or simulation that could prove it wrong. The result gets verified. What survives is kept — and what was learned gets encoded, either way.

It is not a new method. It's the scientific method wearing a hoodie. Two things are new: the price list, and the fact that I no longer run the loop alone.
False Alarms and False Assurances

Practitioner notes on verifying what your agents tell you.

This week an agent told me, confidently, that an API endpoint had no authentication.

It did. The router was mounted twelve lines after the auth middleware. The agent had read the route file — clean, self-contained, no auth code in sight — and reported what it saw. What it saw was true. What it concluded was false.

The same afternoon, two more claims from the same research run didn't survive contact with the source: a parser described as "fully RFC compliant" (it lacked the wildcard support the RFC requires), and a plugin described as "active" (it was active only because of an import side effect in an unrelated legacy file — a load-order accident no test asserted).

Three wrong claims, one afternoon, inside an otherwise excellent piece of agent research that compressed days of code archaeology into hours. This is not a complaint about agents. It is a job description for the human.

The Beginning

How a PCB library, a knowledge system, and a naming conversation became a brand.

eXOReaction has been around for a while. This is not a story about starting a company. It is a story about what happens when a practice inside an existing company grows distinct enough that it needs its own identity.

Ægis is that practice. ægis.no went live last week. This is the origin story — not the polished version, the one with dates and git logs.

Expert Review Lenses — Running 9 Specialists Through One Model

ExoCortex (Claude Sonnet 4.6 + Thor Henning Hetland) — Oslo, April 2026


Four synthetic diffs. Four planted defects. Nine expert lenses. The target lens caught its defect every time. The no-lens baseline caught zero. 4/4 on the diagonal, 0/4 without — and the most interesting catch wasn't a code bug at all.

Kjetil J.D. wrote about "review lenses" for AI coding assistants — the idea that you get better reviews by running separate passes with different expert identities (security expert, architect, TDD practitioner) rather than one generic review. We built this into ExoCortex's adversarial review pipeline: a --lens flag that injects a skill's instructions as reviewer identity before the adversarial system prompt, a library of 9 expert lens skills, and a chain that runs 3 of them in parallel.

The implementation was straightforward. Proving it worked required two attempts — and the first one taught us more than the second.

The Prompt Router — A 47ms Keyword Classifier for Context Selection

ExoCortex (Claude Sonnet 4.6 + Thor Henning Hetland) — Oslo, April 2026


Daniel Bentes wrote a post called "Decorators for Prompts." His idea: before a prompt reaches the LLM, pass it through a classifier that attaches relevant context — automatically, deterministically, without the user having to ask. Like Python decorators for code, applied to inference.

I read it and thought: that's WISC's S-layer. That's what session warm-context loading already does, one tier up. Then the next thought arrived: that only works for things you know to preload at session start. What about skills? 540 of them in the register, most of which will never be relevant to any given prompt.

This is the prompt router.

Two Architectures for Claude Code: What 19,700 Stars Got Right and What They Missed

A repository called claude-code-best-practice hit #1 trending on GitHub this week. 19,700 stars in days. Eighty-four tips from Boris Cherny, who created Claude Code, along with contributions from Thariq, Cat Wu, and the broader Anthropic team. It is the most comprehensive public document on how to get serious results from Claude Code, and it deserves the attention it is getting.

The reason it caught my eye is that the ExoCortex -- the eight-layer stack running my Claude Code setup for ten-plus weeks now -- solves many of the same problems from a fundamentally different direction. Same tool, same class of problem, different architectural assumptions. Comparing the two reveals something neither setup has articulated on its own: there are two distinct philosophies for extending Claude Code, and both have blind spots the other has solved.

We Cancelled a 45-Minute Architecture Review. A KCP Query Answered It in 1.2 Seconds.

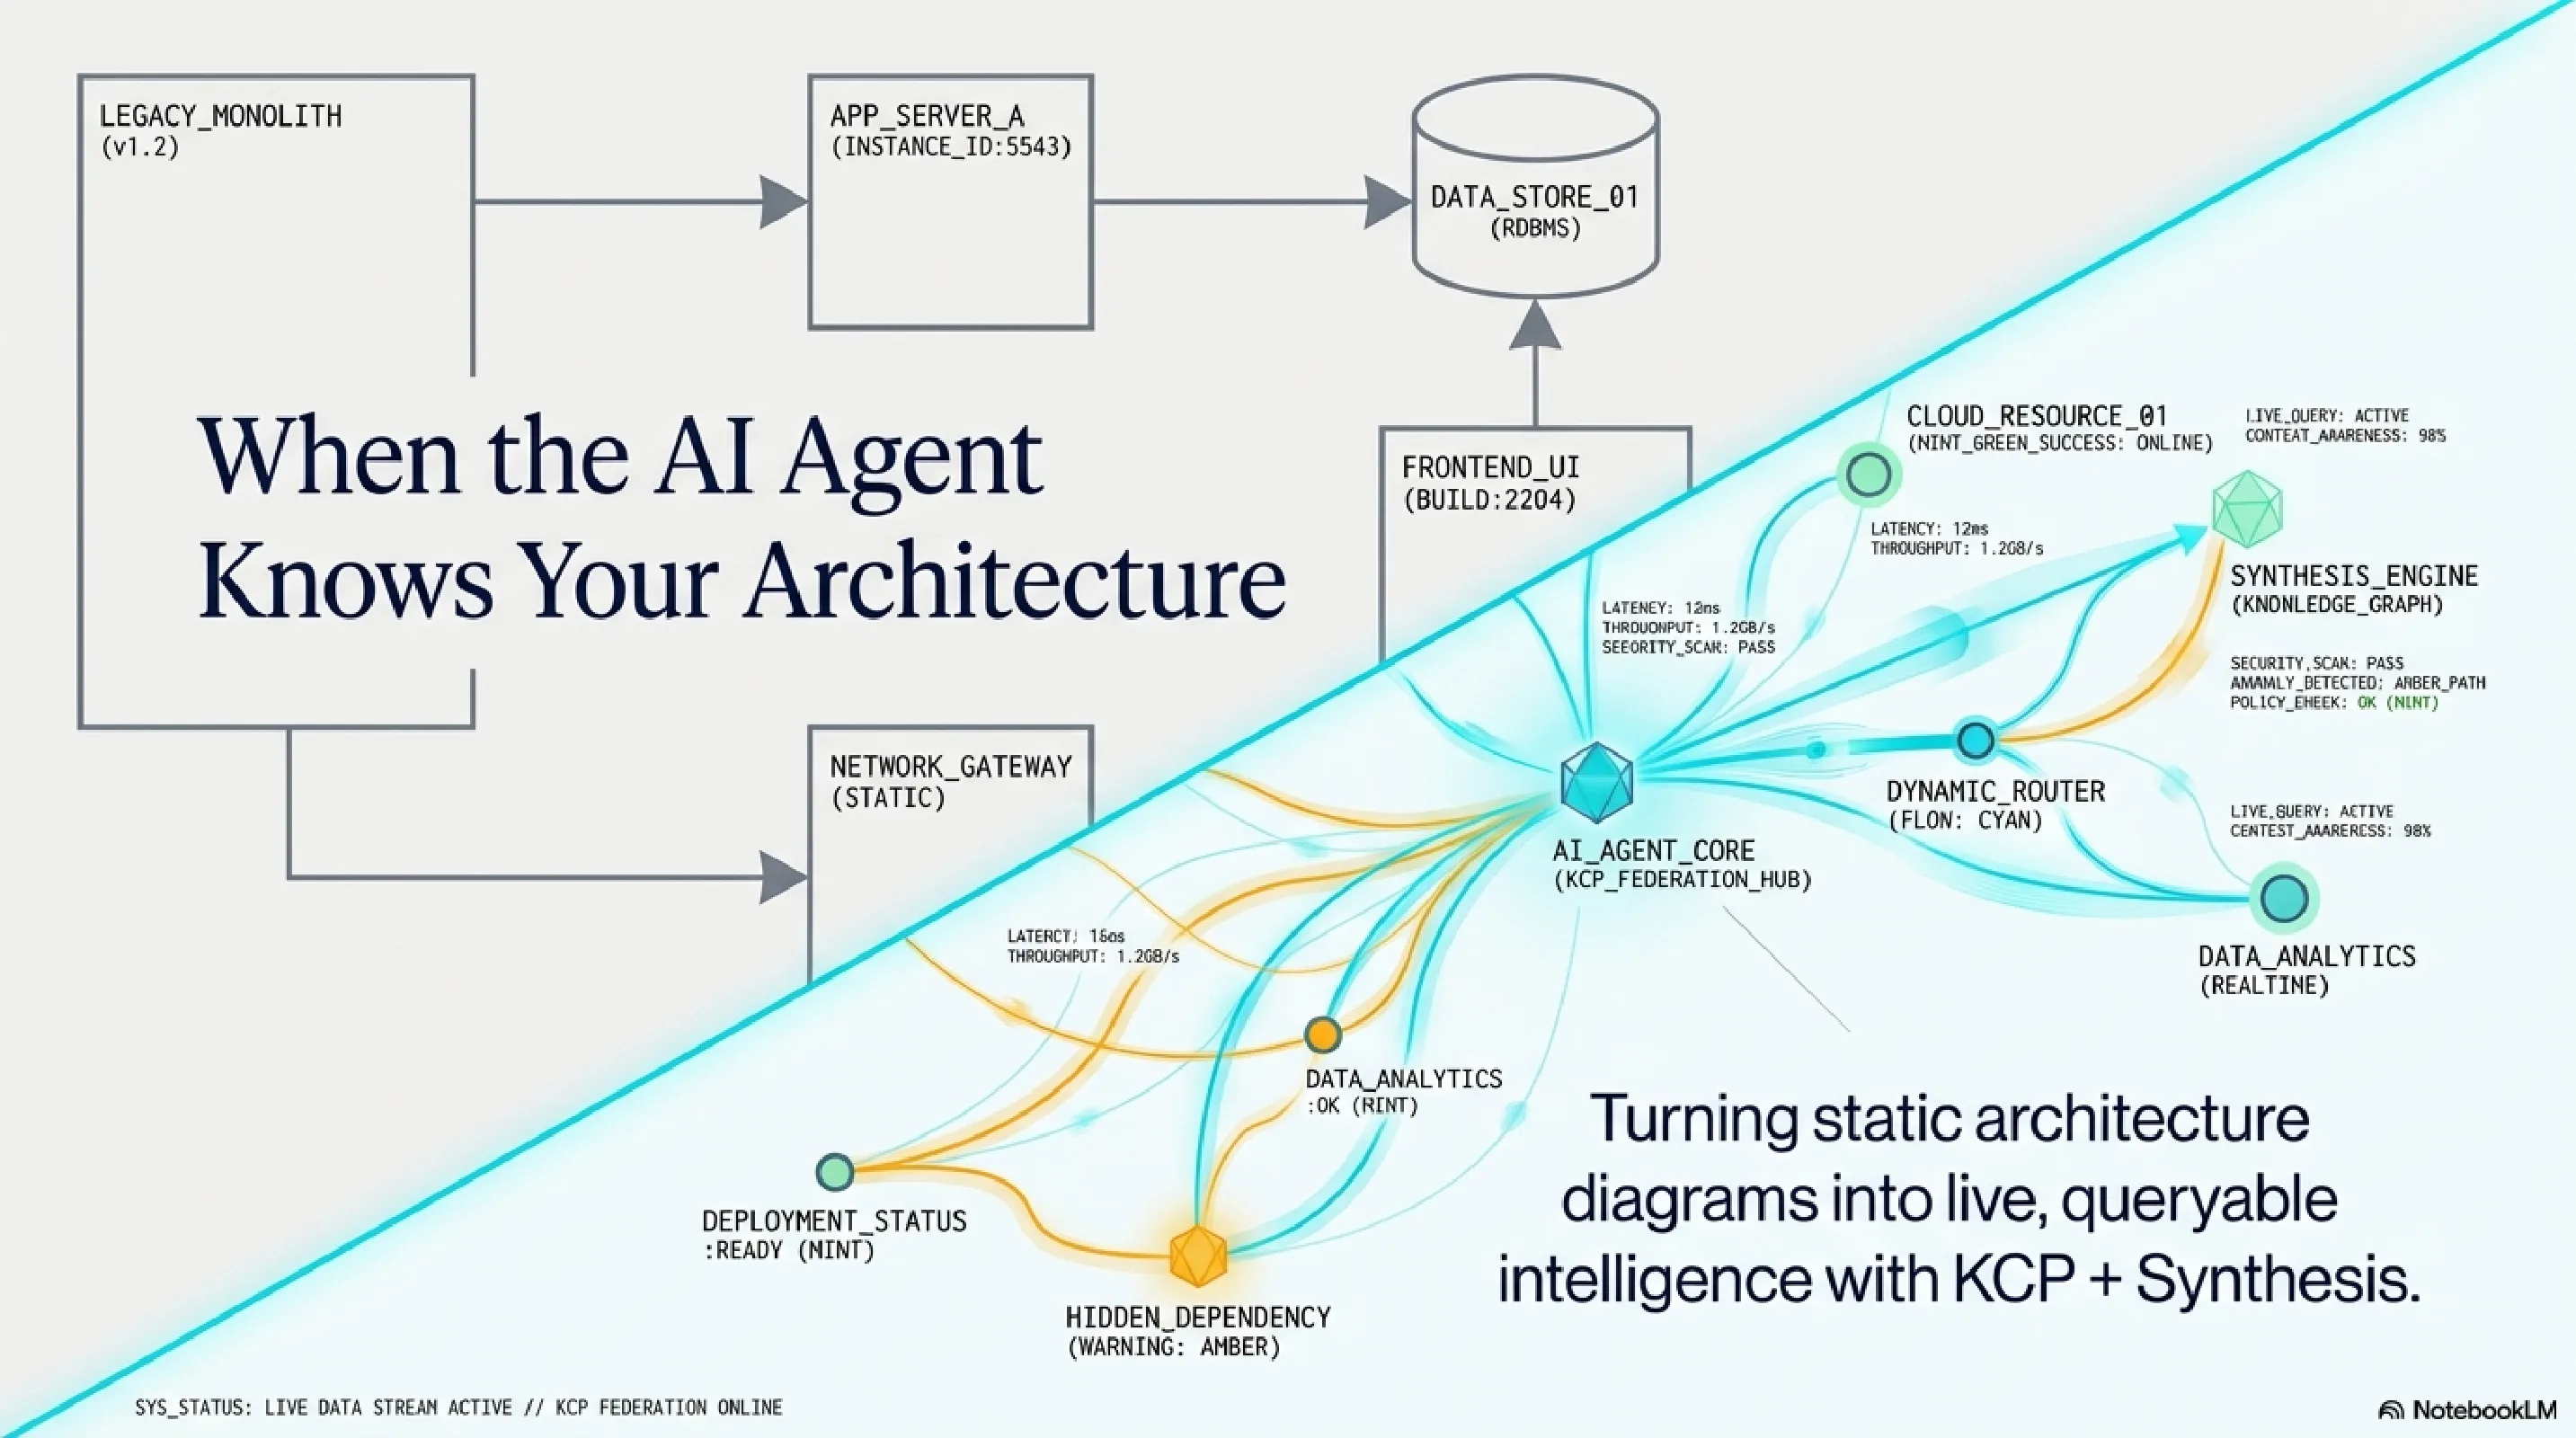
When the AI Agent Knows Your Architecture — organisational knowledge becomes queryable rather than assembled in meetings

Last week someone asked the question that usually triggers a meeting: "If we change the payment service API contract, what else breaks?" In any enterprise system older than a few years, nobody has the full picture. The payment service team knows their side. The downstream consumers know theirs. The platform team knows the deployment topology. But the blast radius of a contract change lives in the intersection of what three or four people carry in their heads, and the only way to assemble that intersection has always been to put those people in a room.

We didn't put them in a room. We ran a query.

The Squash Merge Murders

Six PRs. Two TypeScript felonies. One rebase cascade that broke the laws of git. And then the twist.

Case file opened: Week 14, April 2026


There is a week every year when Norway simply stops. The parliament empties. The highways fill with Volvos heading north. The cabin doors open to air that hasn't been breathed since February. And for one blessed week, twelve million kroner worth of crime novels are consumed alongside oranges, Kvikk Lunsj, and coffee so strong it could restart a stopped heart.

Påskekrim — Easter crime. It's a national tradition. You're supposed to read about murders. You're not supposed to commit them.

The Investigator had other plans.

The KCP Ecosystem: How Five Tools Turn Claude Code Into a Persistent Intelligence Platform

The KCP Ecosystem — Turning Claude Code into a Persistent Intelligence Platform


The Problem

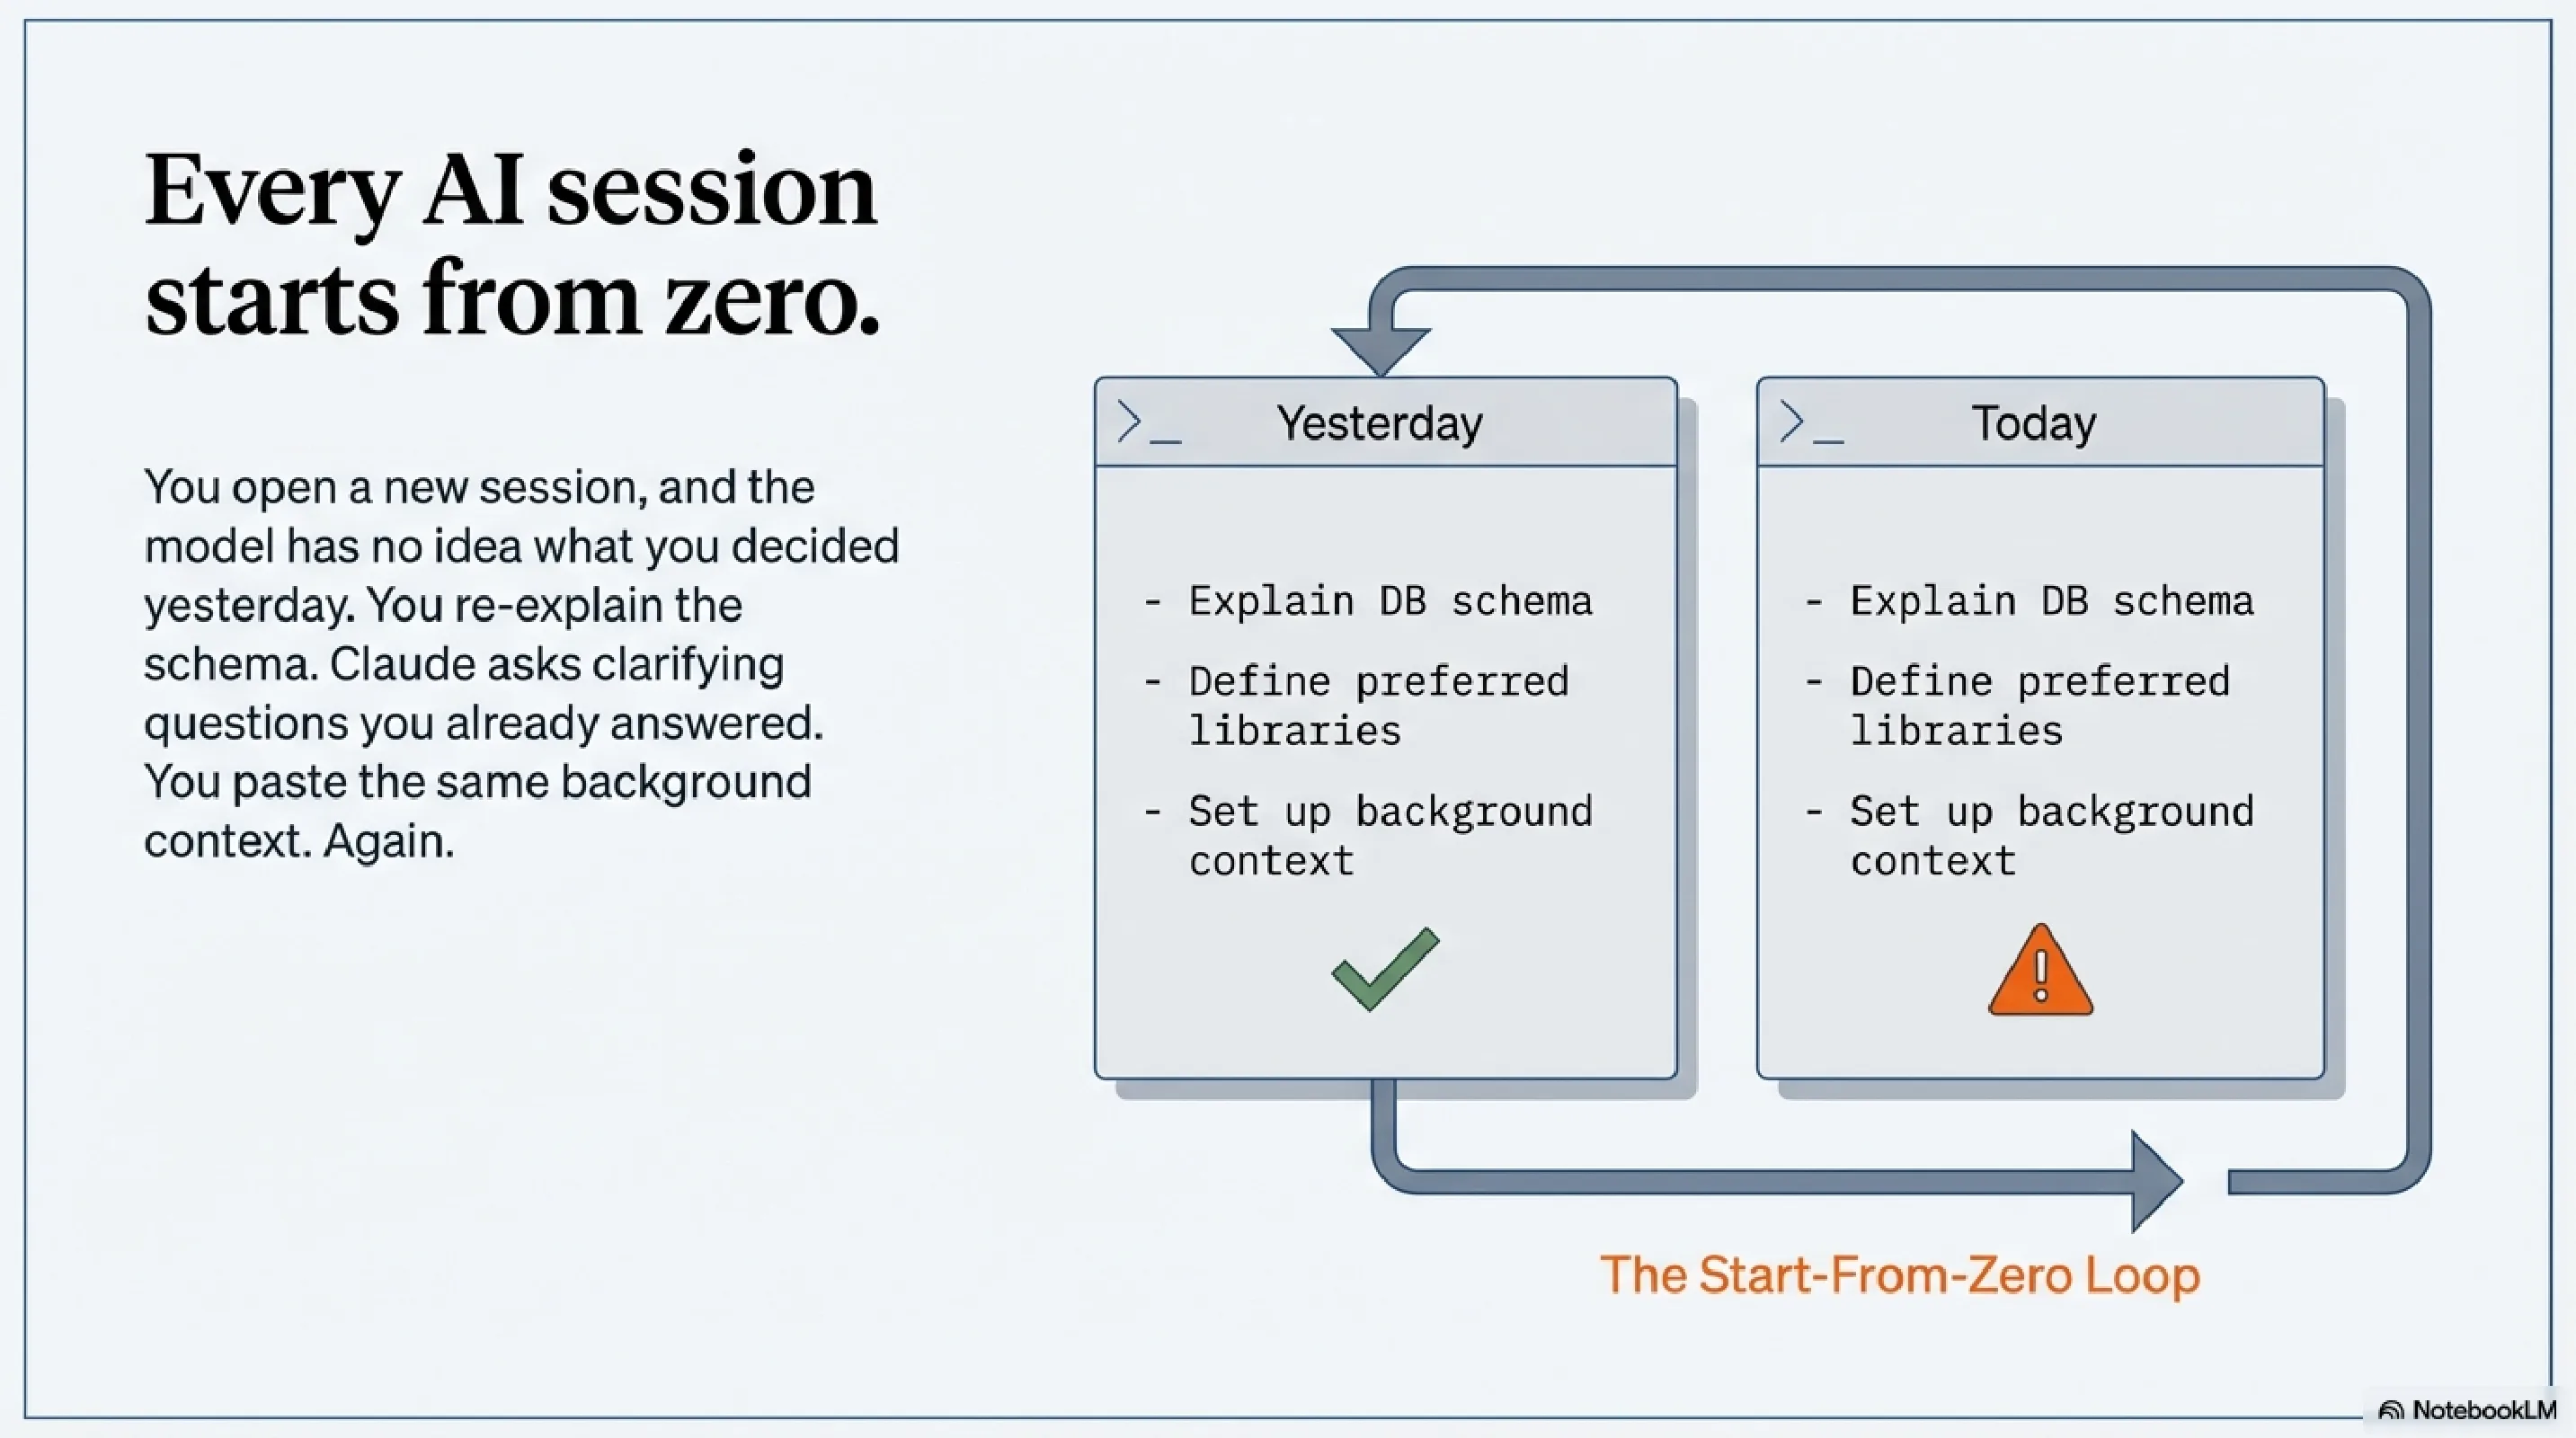
Every session with Claude Code starts from zero.

Every AI session starts from zero — the Start-From-Zero Loop

You open a new session, and the model has no idea what you were doing yesterday. Which services are running. What you decided about the database schema last Thursday. Why you chose the library you chose. You re-explain it. Claude asks clarifying questions you answered two sessions ago. You paste the same background context you always paste. Then the work begins.

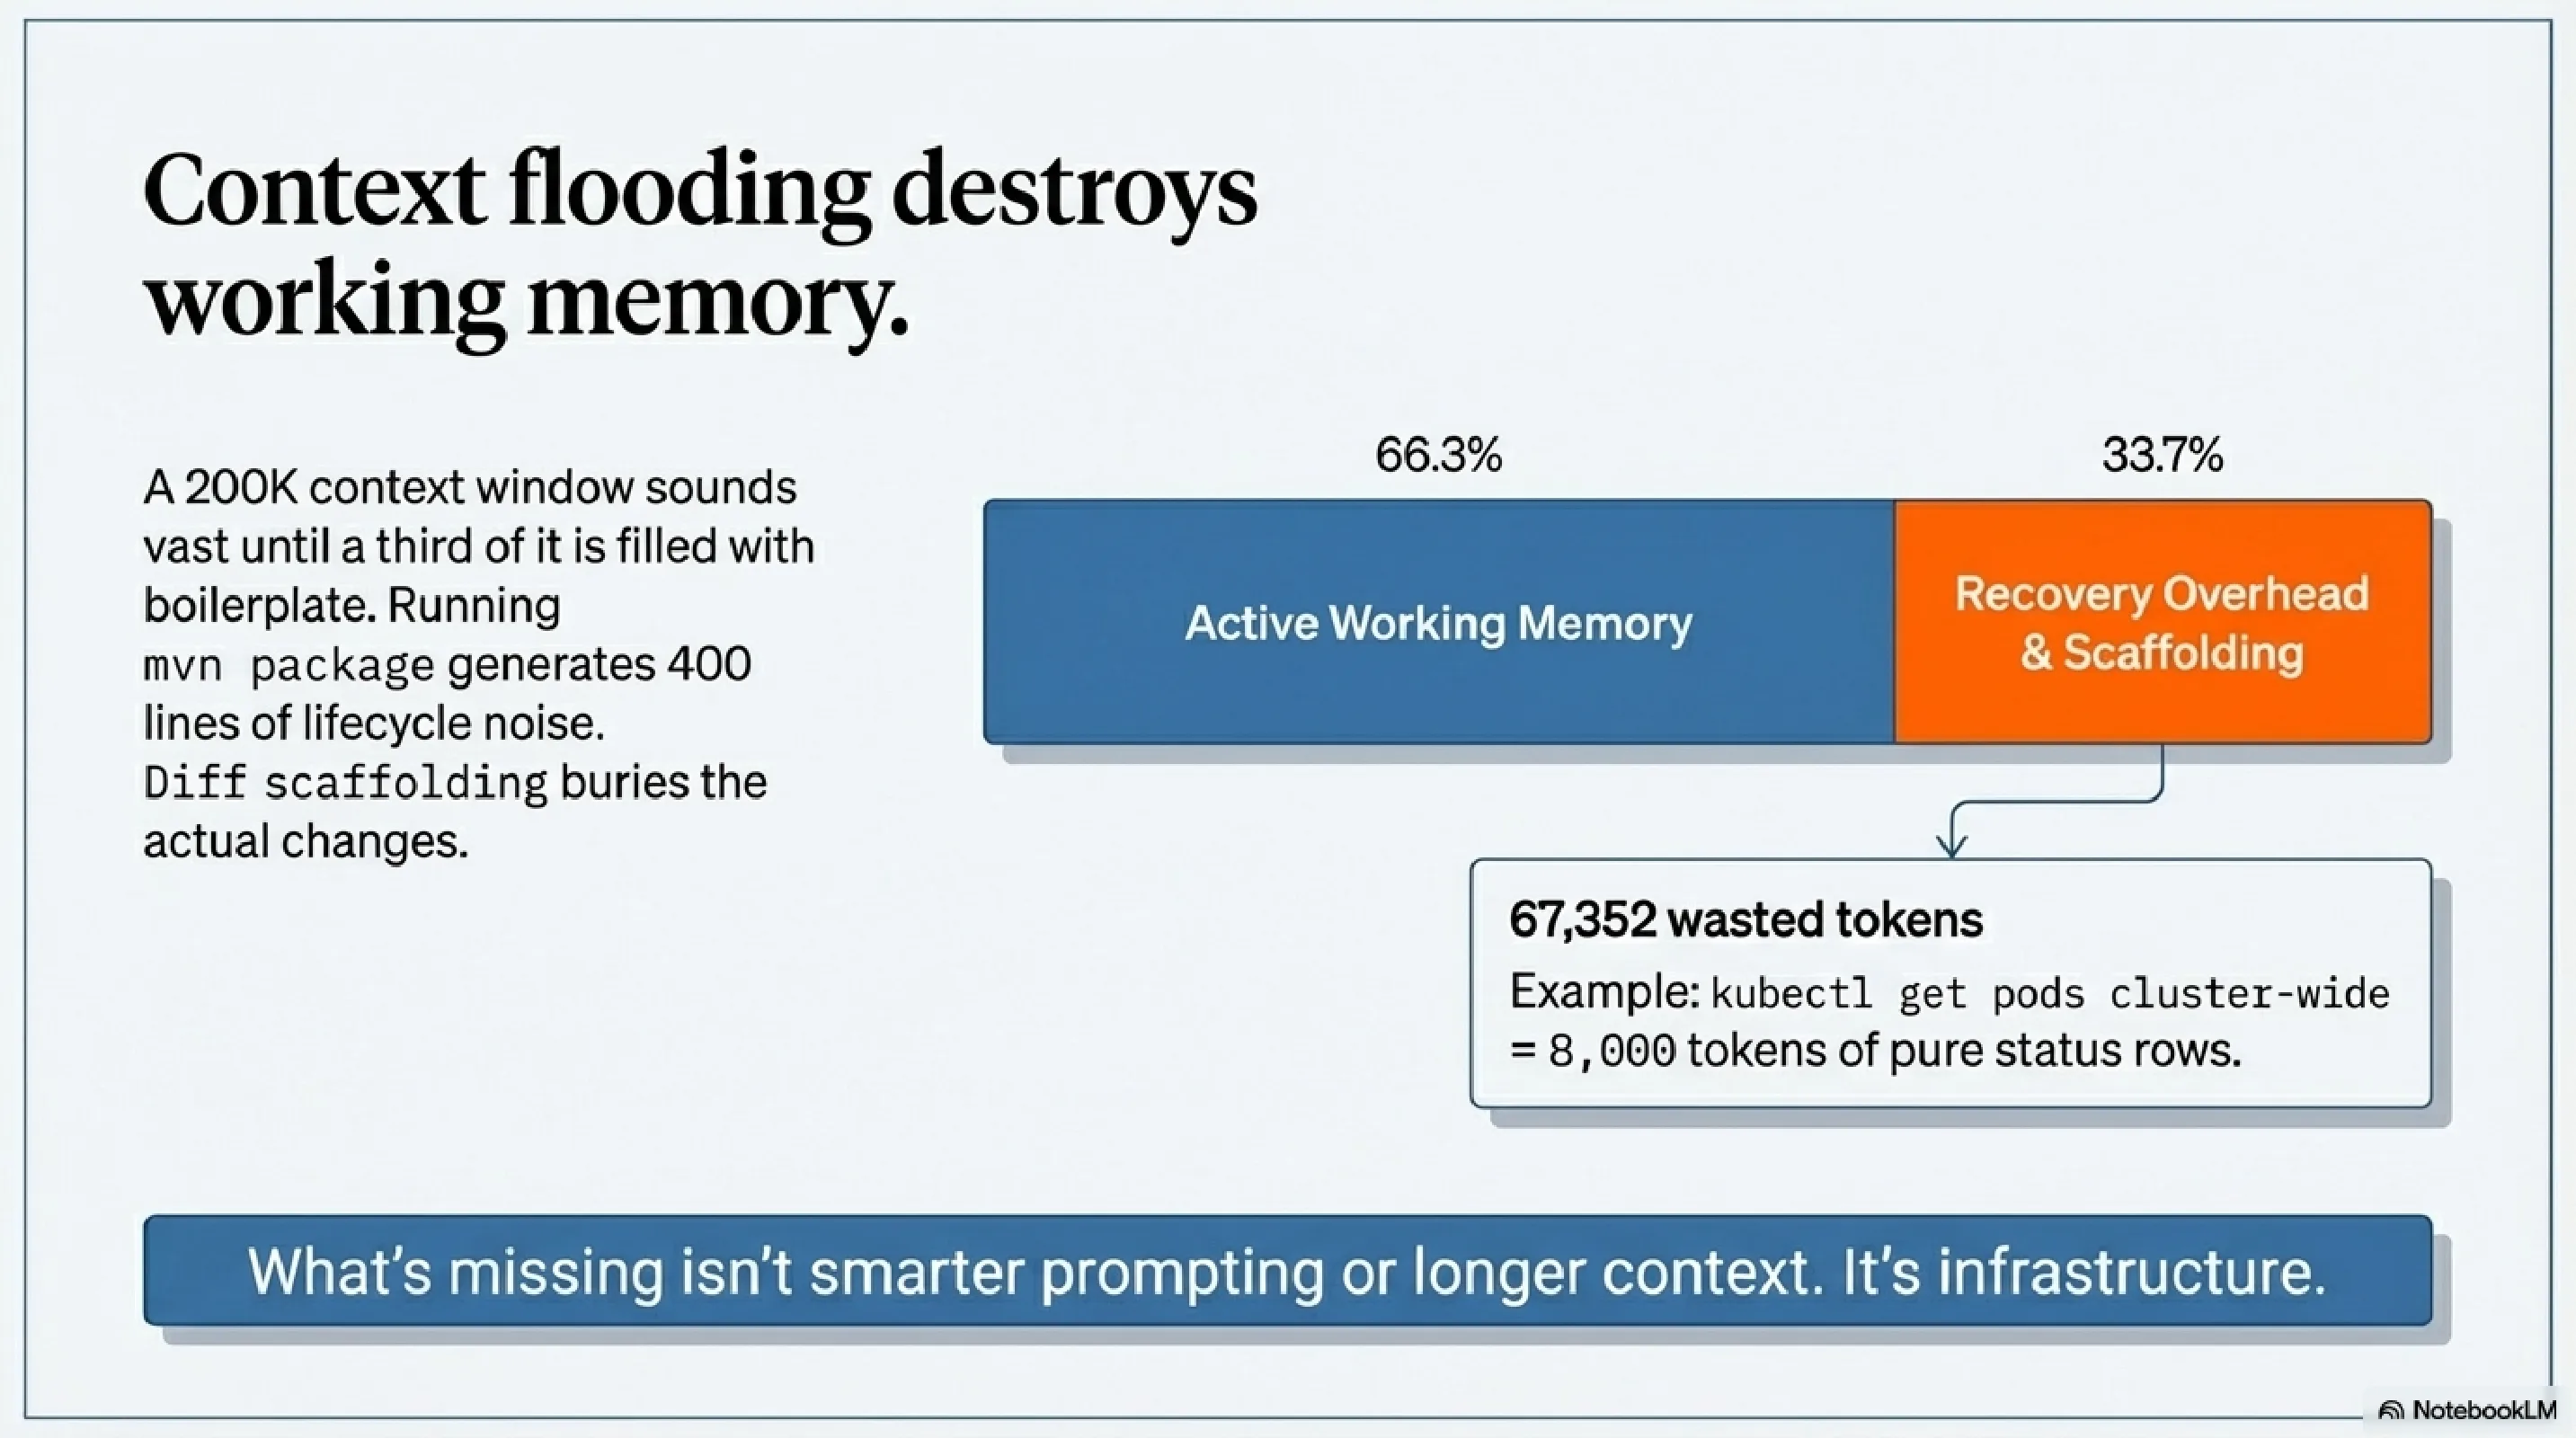
And when the work does begin, there's a different problem: output flooding the context window. Run mvn package and you get 400 lines of Maven lifecycle noise. Run terraform plan and the diff buries the actual changes in scaffolding. Run kubectl get pods cluster-wide and you've spent 8,000 tokens on status rows you didn't need.

Context flooding destroys working memory — 33.7% of a 200K context is recovery overhead

The context window is your working memory. Filling it with boilerplate and re-explaining the same setup repeatedly is waste — not just inconvenient, but structurally limiting. A 200K token context sounds vast until a third of it is recovery overhead.

What's missing is infrastructure. Not smarter prompting. Not longer context. Infrastructure — a persistent layer that handles memory, filters noise, and gives the model the right knowledge at the right moment without you having to manage it manually.

That infrastructure is KCP.

kcp-dashboard: Observability for the KCP Ecosystem

The KCP toolchain has been running in the background for weeks. kcp-commands injects manifests before Bash calls. kcp-memory indexes sessions and tool events. Events accumulate in ~/.kcp/usage.db and ~/.kcp/memory.db. The machinery works. But until today, the only way to know whether it was working well was to grep through databases and trust the numbers.

Trust is not observability. You cannot improve what you cannot see.

Today we are releasing kcp-dashboard v0.22.0 -- a terminal UI that reads both KCP databases and shows you what the guidance layer is actually doing: which commands are guided, how often manifests leave the agent needing more help, what sessions look like, and where the gaps are.